StepFun AI Pricing 2026: What Does Step Actually Cost?
Direct answer
StepFun sits in the high-efficiency corner of China's AI model market. Its models use sparse Mixture-of-Experts (MoE) architectures that activate approximately 11 billion parameters out of roughly 196 billion total parameters per inference step. In plain terms, you get a big model's brain while only paying for a small slice of it to think.
On StepFun's official pay-as-you-go developer catalog, pricing per million tokens looks like this:
| Model | Input (cache miss) | Input (cache hit) | Output |
|---|---|---|---|
step-3.5-flash | $0.10 | $0.02 | $0.30 |
step-3.7-flash | $0.20 | $0.04 | $1.15 |
Here's what that means in practice:
- High-throughput workloads stay remarkably inexpensive. Processing 400M input tokens and generating 100M output tokens costs just $70 per month on Step 3.5 Flash and $195 per month on Step 3.7 Flash.
- Output tokens are the main cost driver. Output is billed at 3x the input price on Step 3.5 Flash, and 5.75x on Step 3.7 Flash. Prompt caching cuts cached input by 80%, but it can't discount output tokens.
- Open weights under Apache 2.0. Both models, including the multimodal flagship Step 3.7 Flash, are available under the permissive Apache 2.0 open-source license.
- Self-hosting rarely beats the API at these prices. StepFun's cloud inference is so heavily discounted that renting enterprise GPU instances to self-host only becomes cost-competitive at volumes exceeding tens of billions of tokens per month.
1. Current models and architecture overview
StepFun offers two primary production endpoints, plus a specialized variant:
| Model ID | Role (StepFun's wording) | Parameters | Context | Input | Weights |
|---|---|---|---|---|---|
step-3.7-flash | Flagship multimodal reasoning model | 198B total (196B language backbone + 1.8B vision encoder), about 11B active | 256K | Text, image, video | Open, Apache 2.0 |
step-3.5-flash | High-speed reasoning model for agent and coding tasks | 196.81B total, about 11B active | 256K (262,144) | Text | Open, Apache 2.0 |
step-3.5-flash-2603 | Version tuned for high-frequency agent scenarios; same price as 3.5 Flash | Not stated in the cited public documentation | 256K (per Artificial Analysis) | Text | Not specified by the vendor |
Key architectural observations:
Step 3.7 Flash has configurable reasoning effort (low, medium, high), so you can cap chain-of-thought token generation on routine requests. That's a handy dial when you don't need the model to ponder the meaning of a simple classification.
On Step 3.5 Flash, StepFun notes in its technical model cards that complex coding queries may need slightly longer solution paths than monolithic models like Gemini 3.0 Pro. The practical takeaway: benchmark real-world task completion on your own workload instead of assuming output lengths will match.
Rate limits and concurrency:
Developer tiers scale automatically with your cumulative top-up history. A modest initial $15 top-up immediately unlocks 100 concurrent connections, 1,000 requests per minute, and 20 million tokens per minute. That's plenty of headroom for a growing SaaS integration.
Multimodal pricing:
StepFun charges a flat rate of 400 tokens per image. On Step 3.7 Flash ($0.20/M input), processing 1,000 images consumes just 400,000 tokens, which costs a negligible $0.08.
2. Pay-as-you-go economics
StepFun uses a straightforward prepaid model: usage is deducted from your balance at the active model's per-token rate. No surprise invoices, which is always nice.
Real workloads
To make monthly budgets concrete, here are four common application profiles:
| Workload | Formula (Step 3.5 Flash) | 3.5 Flash | 3.7 Flash |
|---|---|---|---|
| A: 1M in + 250K out | 1 × 0.10 + 0.25 × 0.30 | $0.175 | $0.4875 |
| B: 10M in + 3M out | 10 × 0.10 + 3 × 0.30 = 1.00 + 0.90 | $1.90 | $5.45 |
| C: 400M in + 100M out (monthly) | 400 × 0.10 + 100 × 0.30 = 40 + 30 | $70.00 | $195.00 |
| D: 100M in + 20M out, 80% cache hits | 80 × 0.02 + 20 × 0.10 + 20 × 0.30 = 1.60 + 2.00 + 6.00 | $9.60 | $30.20 |
| D with no caching | 100 × 0.10 + 20 × 0.30 | $16.00 | $43.00 |
Take a look at Workload C. Running continuous 24/7 background processing (roughly 190 tokens per second) costs only $70 per month on Step 3.5 Flash. That's less than many people spend on forgotten subscriptions.
3. Caching economics
StepFun turns on prompt caching automatically for requests where the input prefix exceeds 256 tokens. Cached tokens are billed at an 80% discount (20% of the standard input price) across text, system instructions, and multimodal image arrays:
| Cache-hit share | 3.5 Flash | 3.7 Flash |
|---|---|---|
| 0% | $16.00 | $43.00 |
| 50% | $12.00 | $35.00 |
| 80% | $9.60 | $30.20 |
| 95% | $8.40 | $27.80 |
Best practices for prompt caching:
- Put permanent system prompts and tool schemas at the start of your message array.
- Cache eviction is least-recently-used (LRU), so frequent API calls keep your cache warm.
- Check the
usage.cached_tokensfield in API responses to monitor your live cache performance.
4. Step Plan: credits, tiers and what we can and cannot calculate
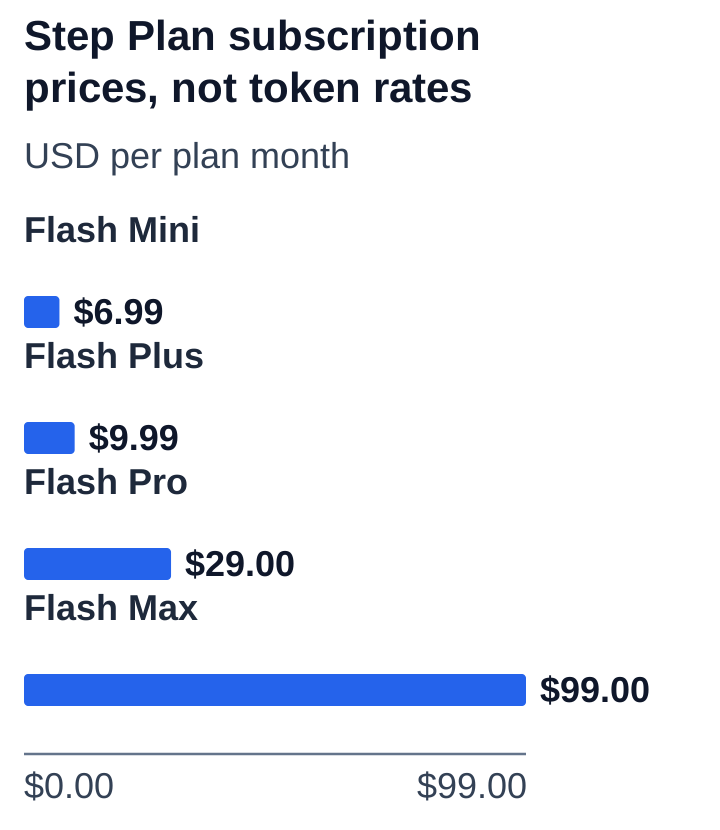
If you're an individual developer or creator using coding assistants like Cline, Roo Code, or Claude Code, StepFun offers subscription tiers called "Step Plan," accessed through dedicated endpoints:
| Tier | Monthly | Quarterly | Yearly | Credits per month |
|---|---|---|---|---|
| Flash Mini | $6.99 | $18.99 | $69.99 | 400M |
| Flash Plus | $9.99 | $26.99 | $95.99 | 1,600M |
| Flash Pro | $29 | $79 | $289 | 8,000M |
| Flash Max | $99 | $269 | $989 | 40,000M |
StepFun documents a nominal reference conversion rate where $1 corresponds to approximately 7 million Credits:
| Tier | Price | Credits | Nominal implied value at 7M Credits/$ | Nominal multiple of price (not verified savings) |
|---|---|---|---|---|
| Flash Mini | $6.99 | 400M | ≈ $57 | 8.2× |
| Flash Plus | $9.99 | 1,600M | ≈ $229 | 22.9× |
| Flash Pro | $29 | 8,000M | ≈ $1,143 | 39.4× |
| Flash Max | $99 | 40,000M | ≈ $5,714 | 57.7× |
Treat those multiples as a nominal reference point, not proven savings. They show how the credits convert on paper, not what you'll actually save.
Operational rules for Step Plan subscriptions:
- Personal developer use: The plan is designed for desktop coding environments and personal tools, not for multi-tenant commercial backend infrastructure.
- Monthly expiration: Plan credits reset each billing cycle and don't accumulate or roll over.
- Dedicated routing: It connects through
api.stepfun.ai/step_plan/v1, which keeps interactive developer usage separate from your standard API production keys.
5. The open weights and the license
Both Step 3.5 Flash and Step 3.7 Flash are published on Hugging Face and GitHub under the Apache License 2.0. That license permits commercial deployment, fine-tuning, and software integration without restrictive revenue-share clauses or proprietary usage tiers.
Self-hosting considerations:
The weights are free, but the hardware isn't. Self-hosting a ~198B MoE model takes a dual or quad enterprise GPU node (such as 4x NVIDIA A100/H100 80GB cards) to hold the quantized checkpoints in high-speed VRAM. At typical cloud GPU rental rates ($8 to $16 per hour, or $5,800 to $11,500 monthly), a team has to generate tens of billions of tokens every month to match StepFun's hosted API economics. For almost all teams, calling the hosted API is far more economical.
6. Practical recommendations
- Use Step 3.5 Flash for high-speed agent loops. Its $0.10/$0.30 pricing makes it a good fit for recursive tool calling, automated testing, and background classification.
- Use Step 3.7 Flash for multimodal analysis. Native 256K context and flat 400-token image pricing make document OCR and visual reasoning affordable.
- Tune your reasoning settings. Set reasoning effort to low or medium on Step 3.7 Flash for deterministic workflows, so you don't get runaway output token generation.