Xiaomi MiMo API vs Self-Hosting: Does MIT-Licensed AI Actually Save Money?
The short answer
Xiaomi caught a lot of AI engineers off guard by publishing MiMo-V2.5-Pro's weights under the permissive MIT license. Anyone with an internet connection can download this 1.02-trillion-parameter foundation model and deploy it. The catch is that free weights don't make running the infrastructure cheap.
- The official hosted API rate is remarkably low. Xiaomi's developer API charges $0.435 per million input tokens, $0.87 per million output tokens, and an automatic $0.0036 per million cached-input tokens. For an active production workload processing 400M input tokens and 100M output tokens each month, your hosted API invoice comes to just $261.
- The minimum viable self-hosted cluster is an 8-GPU node (NVIDIA H200 or B200 class). Renting a dedicated 8-GPU node around the clock at prevailing enterprise cloud rates costs roughly $10,278 to $31,171 per month, and that's before network egress, storage, or DevOps engineering hours.
- Self-hosting wins financially only under fairly specific conditions: heavy input volume, minimal prompt caching, low-cost spot or owned GPU capacity, and sustained cluster utilization above break-even thresholds (typically 26% to 77%). Once you use prompt caching well on the API, self-hosting almost never breaks even on price alone.
- Operational autonomy is the real reason to run it yourself. If strict data residency rules keep your data inside your virtual private cloud, or you plan to fine-tune the weights for proprietary workflows, self-hosting is an architectural necessity no matter what the token math says.
1. What MiMo-V2.5-Pro actually is
MiMo-V2.5-Pro is Xiaomi's entry into frontier-class open-weight models, going head to head with MoE architectures like DeepSeek and Moonshot's Kimi:
| Item | Details |
|---|---|
| Model name | MiMo-V2.5-Pro (Xiaomi API ID mimo-v2.5-pro; Hugging Face XiaomiMiMo/MiMo-V2.5-Pro; OpenRouter xiaomi/mimo-v2.5-pro) |
| Architecture | Mixture-of-Experts, 1.02T total / 42B active parameters; 384 routed experts, 8 used per token; 70 layers |
| Context | Up to 1M tokens (the Base variant is 256K) |
| Weights | FP8 (E4M3) mixed precision; the Hugging Face repo totals about 1.03 TB |
| Modality | Text |
| Dates | Xiaomi's open-source announcement is dated April 27, 2026. OpenRouter lists an April 22, 2026 release for API access |
| Status | Xiaomi calls it its most capable model to date. Xiaomi has since opened an invite-only beta of newer "MiMo-X" preview models; their relationship to V2.5-Pro is not documented |
For a sense of scale, Xiaomi's model card benchmarks put MiMo-V2.5-Pro right next to Kimi K2 (1.04T total / 32B active) and DeepSeek V4 Pro (1.6T total / 49B active). This is a genuine trillion-parameter class system.
The naming trap: V2.5 is not V2.5-Pro
Xiaomi ships two similarly named open-weight models that serve different workload tiers. MiMo-V2.5 is a 310B-total / 15B-active multimodal model, while MiMo-V2.5-Pro is the 1.02T text flagship. On Xiaomi's overseas rate card, their pricing differs by more than 3x:
| Model | Input (miss) | Output |
|---|---|---|
mimo-v2.5 | $0.14 | $0.28 |
mimo-v2.5-pro | $0.435 | $0.87 |
When you're sizing a budget or signing a third-party host agreement, double-check that the model strings match character for character. It's a small habit that can save you a very awkward invoice conversation.
2. The license: MIT with standard terms
The official model card on Hugging Face declares license: mit. Xiaomi's leadership confirmed that the MiMo-V2.5 series is MIT-licensed for commercial deployment, continued post-training, and domain-specific fine-tuning, with no proprietary licensing agreement required.
A couple of legal points worth knowing as an engineering lead:
- Commercial rights follow standard MIT provisions: You're free to embed the weights in commercial SaaS applications, as long as the original copyright notice and permission notice accompany distributions of the software. As with all MIT software, the code is provided without warranty or liability.
- The license covers weights, not hosted API endpoints: If you use Xiaomi's managed API or a third-party inference aggregator, each vendor's commercial terms of service and acceptable use policies apply, not the open-source terms.
3. What hosted access costs today
3.1 Xiaomi's official developer rate card
Xiaomi publishes a transparent pay-as-you-go rate card on its international developer portal, in US dollars per million tokens:
mimo-v2.5-pro, overseas | Price per 1M tokens |
|---|---|
| Input, cache miss | $0.435 |
| Input, cache hit | $0.0036 |
| Output | $0.87 |
| Cache write | Free "for a limited time" |
| Web search plugin (overseas) | $5 per 1,000 calls, billed separately |
Independent benchmarking by Artificial Analysis puts effective blended pricing around $0.18 per million tokens under standard agent ratios (70% cache hits, 20% fresh input, 10% output). That's a substantial drop from launch rates, which reflects hardware optimization and prefix-caching improvements across Xiaomi's data centers.
3.2 Third-party hosted endpoints
If you want multi-provider redundancy, several cloud inference hosts serve the same xiaomi/mimo-v2.5-pro weights, either directly or through OpenRouter:
| Provider on OpenRouter | Input | Cache hit | Output | Label |
|---|---|---|---|---|
| Xiaomi | $0.435 | $0.0036 | $0.87 | (matches Xiaomi's own rate card) |
| AtlasCloud | $0.435 | $0.0036 | $0.87 | Third-party host |
| GMICloud (30% off $0.435 / $0.87) | $0.3045 | $0.0028 | $0.609 | Promotional discount |
| NovitaAI (8% off) | $0.4802 | $0.003956 | $0.9605 | Third-party host |
| StreamLake | $0.522 | $0.00432 | $1.044 | Third-party host |
| DigitalOcean | $0.48 | $0.096 | $1.80 | Third-party host |
| DeepInfra (list $1.00 / $0.20 / $3.00; 61% off shown) | $0.39 | $0.078 | $1.17 | Promotional discount |
3.3 International purchasing and billing
Xiaomi's developer portal accepts international credit cards, Google Pay, and Apple Pay, and settles in USD. You don't need Chinese domestic banking credentials or ICP registration. Account balances are refundable, so it's easy for international teams to kick the tires without much commitment.
4. Workload cost calculations
To get a feel for real-world costs, we modeled four representative production workloads using Xiaomi's official rate card ($0.435 input / $0.0036 cache-hit / $0.87 output), alongside promotional aggregator benchmarks:
| Workload | Formula (Xiaomi native) | Xiaomi native | GMICloud promo |
|---|---|---|---|
| A: 1M in + 250K out | 1 × 0.435 + 0.25 × 0.87 | $0.6525 | $0.4568 |
| B: 10M in + 3M out | 10 × 0.435 + 3 × 0.87 = 4.35 + 2.61 | $6.96 | $4.872 |
| C: 400M in + 100M out (monthly) | 400 × 0.435 + 100 × 0.87 = 174 + 87 | $261.00 | $182.70 |
| D: 100M in + 20M out, 80% cache hits | 80 × 0.0036 + 20 × 0.435 + 20 × 0.87 = 0.288 + 8.70 + 17.40 | $26.39 | $18.49 |
| D without caching, for reference | 100 × 0.435 + 20 × 0.87 | $60.90 | $42.63 |
In Workload D, caching cuts monthly inference spend by 57%. Cached input costs less than half a cent per million tokens ($0.0036/M), so apps that keep stable system prompts, schema definitions, and retrieval context get big structural savings almost for free.
5. Self-hosting economics
5.1 Memory footprint vs active compute
MiMo-V2.5-Pro's Mixture-of-Experts design routes each token through 8 of 384 experts, so roughly 42B active parameters run per forward pass. Here's the gotcha: routing is dynamic across tokens, so the entire 1.02T parameter footprint has to stay resident in VRAM at all times.
At FP8 precision, the weights alone need roughly 1,030 GB of GPU memory, before you've set aside a single megabyte for KV cache, batch activations, or CUDA runtime overhead.
5.2 Documented deployment configurations
80GB GPUs can't hold 1.03 TB of weights, so a standard 8x H100 system won't cut it without multi-node tensor parallelism:
| Setup | Total GPU memory | Source | Status |
|---|---|---|---|
| 8× H100 80GB | 640 GB | n/a | Cannot hold ~1.03 TB of FP8 weights |
| 16× H100 or H200 (2 nodes × 8, TP=16) | 1,280 GB / 2,256 GB | SGLang cookbook; Xiaomi's model-card example command | Cookbook marks it "not yet verified" |
| 8× H200 141GB, one node, TP=8 | 1,128 GB | vLLM recipe linked from Xiaomi's model card | Documented; needs a special vLLM build |
| 8× B200 192GB, one node, TP=8 | 1,536 GB | SGLang cookbook | Marked "verified"; benchmarked |
| TPU v7x, 16 chips | n/a | SGLang (sgl-jax) | Marked "verified" |
On an 8x H200 node (1,128 GB VRAM total), you're left with about 40–50 GB after loading weights. That's tight headroom for context memory when serving multiple users at once.
5.3 KV cache memory overhead at long context
MiMo's hybrid attention mechanism (10 global layers and 60 sliding-window layers) shrinks the KV cache considerably compared to standard dense transformers. Long contexts still need dedicated memory, though:
| Context per request | KV cache, FP8 | KV cache, BF16 |
|---|---|---|
| 128K tokens | ≈ 3.4 GB | ≈ 6.7 GB |
| 1M tokens | ≈ 25.6 GB | ≈ 51.2 GB |
On an 8x H200 cluster, a single 1M-token prompt eats over half of that remaining 40–50 GB buffer. So if you want to serve full 1M-context requests with reasonable concurrency, you'll need to step up to a 16-GPU cluster (two interconnected 8-GPU nodes).
5.4 Monthly infrastructure commitment
Renting enterprise GPU nodes 24/7 (730 hours per month) sets your baseline fixed monthly cost:
| GPUs | ≈$1.76/GPU-hr (spot-like) | ≈$3.70/GPU-hr (on-demand-like) | ≈$5.34/GPU-hr (B200 spot-like) |
|---|---|---|---|
| 8 | $10,278 | $21,593 | $31,171 |
| 16 | $20,557 | $43,187 | $62,342 |
| 32 | $41,114 | $86,374 | $124,684 |
5.5 Break-even utilization analysis
Here's how self-hosted token generation stacks up against Xiaomi's hosted API rates, and how busy you'd need to keep the cluster to justify it:
| Scenario | Node $/hr | Blended tok/s | Self-host $/1M at 100% | API $/1M | Break-even utilization |
|---|---|---|---|---|---|
| Short-request benchmark (nominal 1K/1K), B200 measured | $42.70 | 4,415 | $2.69 | $0.606 | 443% (never) |
| Agent-style 16K/1K, no MTP, spot-like | $14.08 | 15,898 | $0.246 | $0.461 | 53% |
| Agent-style, no MTP, on-demand-like | $29.58 | 15,898 | $0.517 | $0.461 | 112% (never) |
| Agent-style, MTP accept-length 4, spot-like | $14.08 | 23,225 | $0.168 | $0.461 | 37% |
| Agent-style, MTP accept-length 4, on-demand-like | $29.58 | 23,225 | $0.354 | $0.461 | 77% |
| Same MTP case, but API gets 80% cache hits, spot-like | $14.08 | 23,225 | $0.168 | $0.136 | 124% (never) |
| Same, on-demand-like | $29.58 | 23,225 | $0.354 | $0.136 | 261% (never) |
| Owned server (illustrative), MTP, vs uncached API | $10.15 | 23,225 | $0.121 | $0.461 | 26% (89% vs cached API) |
Self-hosting only beats the API when you're running input-heavy, low-cache workloads on heavily discounted hardware and keeping the cluster continuously busy (37%–77% average utilization). If your workload benefits from prompt caching on the API, the crossover threshold climbs past 100%, which means self-hosting will reliably lose you money.
6. Build & Earn: a developer product on MiMo-V2.5-Pro
To see the unit economics in action, picture an AI pull-request review assistant sold to engineering teams for $29 per seat per month. Each customer runs 300 reviews a month, and each review uses 40,000 input tokens and generates 3,000 output tokens (12.9M tokens total per seat):
| Case | Model cost per customer | Gross margin at $29 |
|---|---|---|
| Base usage, no caching | $6.00 | 79.3% |
| Base usage, 75% cache hits | $2.12 | 92.7% |
| 3× usage (agent loops), no caching | $18.01 | 37.9% |
| 3× usage, 75% cache hits | $6.36 | 78.1% |
| 10× usage, no caching | $60.03 | −107% |
| 10× usage, 75% cache hits | $21.20 | 26.9% |
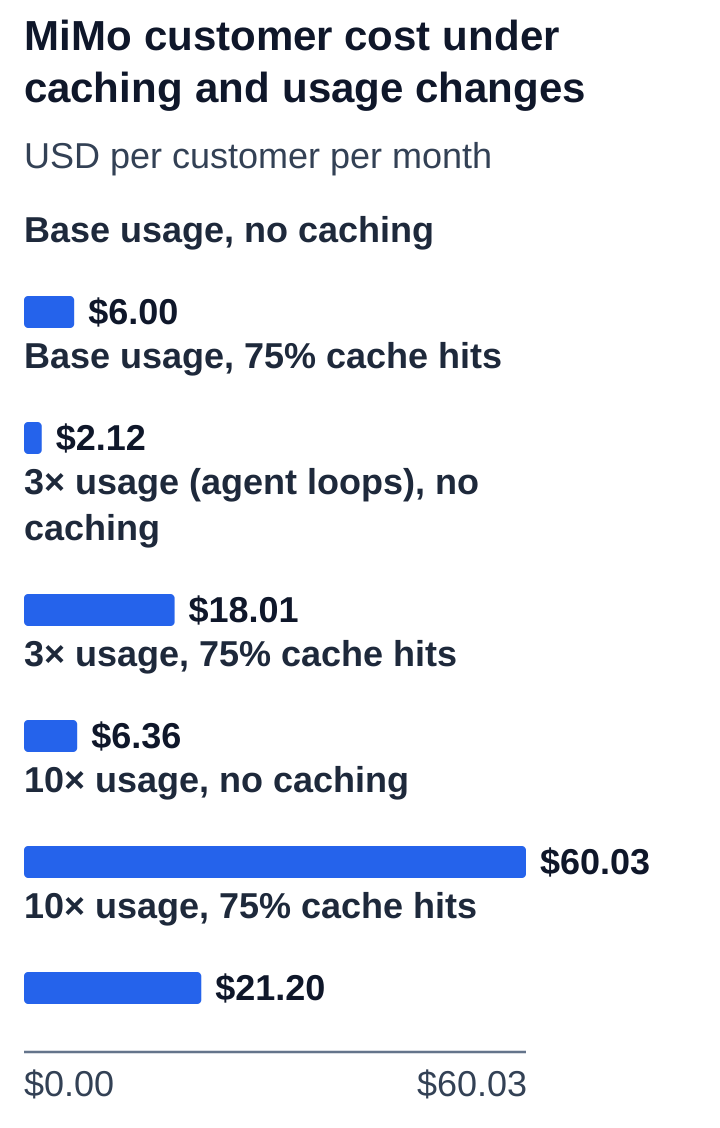
With effective prompt caching (think reusing repository ASTs and file maps), your gross margin stays comfortably above 78% even under heavy usage. Without caching, though, a power user stuck in a continuous agent loop can easily push token costs to $60/month, and suddenly that customer's unit economics go negative. We've all had that one user.
The bottom line: how to make the hosting decision
The MIT license behind MiMo-V2.5-Pro is a big win for developer independence, regulatory privacy, and proprietary fine-tuning. Treating open weights as an automatic cost cut, though, is a trap.
At Xiaomi's current API rates ($0.435 input / $0.0036 cached / $0.87 output), calling the managed endpoint is almost always cheaper, simpler, and lower risk than running an enterprise 8x H200 cluster. Unless your organization processes tens of billions of tokens per month and can keep utilization high around the clock, building on the hosted API gives you far better unit economics.