Tencent Hunyuan 2026: API vs Open Weights — What Does It Really Cost?
Direct answer
Tencent's flagship foundation model, Hunyuan Hy4, offers a rare combination in frontier AI. It's an open-weight 770B parameter Mixture-of-Experts model released under the permissive Apache 2.0 license, and it comes with a hosted API at $0.834 per million input tokens, $2.501 per million output tokens, and $0.042 per million cached tokens.
Among flagship-tier open-weight models, Hy4 is one of the most cost-effective hosted APIs out there. Its output tokens are significantly cheaper than GLM-5.3 ($4.40/M) and Kimi K3 ($15.00/M).
The practical catch: "open weight" doesn't mean "cheap to host yourself." Hy4 has 770 billion parameters (49 billion active per token), so running it locally takes over 512GB of high-speed accelerator memory, even with 4-bit quantization. Unless you're operating at extreme enterprise scale, Tencent's managed cloud API is far more economical than renting dedicated GPU clusters.
The model family
On Hugging Face and GitHub, Tencent documents Hy4's technical specs:
- 770B total parameters, 49B activated per token: The model has 78 transformer layers (1 dense feed-forward layer plus 77 MoE layers with 256 routed experts and 1 shared expert, routing top-8 experts per token).
- Native Multi-Token Prediction (MTP): An auxiliary 10B/0.7B active speculative decoding layer is built in to speed up inference throughput.
- Permissive Apache License 2.0: Some bespoke licenses come with revenue-sharing thresholds. Hy4 doesn't. It grants royalty-free commercial modification and redistribution.
- Generational evolution: Hy4 succeeds Hy3 (295B total / 21B active with a 256K context window), which launched earlier in 2026.
International availability
Tencent Cloud runs an international platform ("Tencent HY Global") with 3D generation and specialized translation APIs (Hunyuan-translation). The general-purpose Hy3 and Hy4 chat and reasoning models are hosted primarily on Tencent's mainland platform (TokenHub / cloud.tencent.com).
If you're building a global service, check regional network latency and account verification requirements before you commit to a deployment. Discovering this after launch is a rough way to spend a Friday.
API pricing
Here's the current hosted developer pricing across the Tencent Hunyuan family:
| Model | Input | Output | Cache-hit |
|---|---|---|---|
| Hunyuan Hy4 (preview, current flagship) | $0.834/M | $2.501/M | $0.042/M |
| Hunyuan Hy3 (current, post-migration) | $0.13/M | $0.53/M | not confirmed |
| Hunyuan TurboS (older, high-speed) | $0.11/M | $0.28/M | not confirmed |
| Hunyuan A13B Instruct | $0.14/M | $0.57/M | not confirmed |
Tencent has adjusted pricing as the models matured. Hy3 moved from an early preview rate to its stable current $0.13/$0.53 rate card. Legacy calls to hy3-preview are now routed seamlessly to the finalized production checkpoint, so you don't need to chase down old endpoints.
Self-hosting economics
Downloading Hy4's weights from Hugging Face is free. Running inference at scale is where the bill shows up, because you need enterprise data-center infrastructure:
- Memory requirements: A 770B-parameter model quantized to 4-bit precision (Q4 GGUF) needs approximately 450GB of raw weights. Add KV cache buffers and runtime overhead, and you need a minimum of 512GB of GPU VRAM. Lower 2-bit quantization can squeeze onto 256GB, but you'll notice degraded reasoning and coding quality.
- Hardware commitment: 512GB of VRAM means an 8x NVIDIA A100 or H100 80GB node. On modern on-demand cloud GPU providers, renting an 8-GPU node typically costs between $15 and $30 per hour, depending on commitment terms and availability.
Break-even analysis: hosted API vs rented GPUs
To see when self-hosting starts to make financial sense, let's compare the numbers.
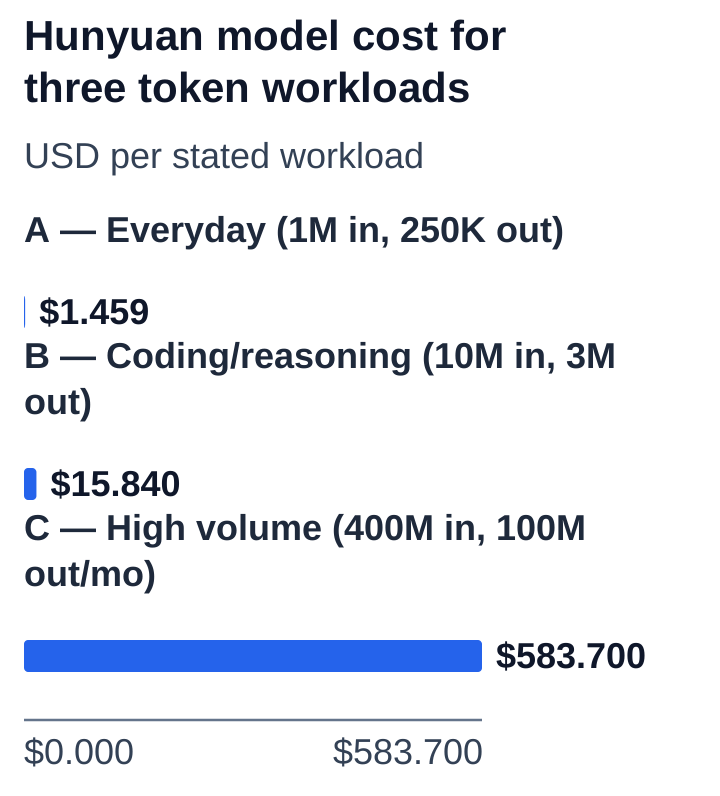
On Tencent's hosted API, a heavy monthly workload of 400M input tokens and 100M output tokens costs: (400 × $0.834) + (100 × $2.501) = $333.60 + $250.10 = $583.70 per month.
Now consider renting an 8x 80GB GPU instance. At an illustrative $20 per hour running 24/7 (730 hours per month), the server bill alone comes to $14,600 per month. That's before setup labor, networking, and storage overhead. At 500 million tokens per month, the hosted API is roughly 25 times cheaper than renting hardware.
Self-hosting only approaches cost parity when your monthly token consumption reaches the tens of billions and your private GPU cluster runs at near 100% continuous utilization. For virtually any startup, agency, or enterprise pilot, calling the hosted API is the smarter economic choice.
Real workload calculations (API only)
If you're building on the hosted Hy4 API, monthly token costs stay very predictable across standard production tiers:
| Workload | Formula | Cost |
|---|---|---|
| A — Everyday (1M in, 250K out) | (1×$0.834) + (0.25×$2.501) | $1.459 |
| B — Coding/reasoning (10M in, 3M out) | (10×$0.834) + (3×$2.501) | $15.84 |
| C — High volume (400M in, 100M out/mo) | (400×$0.834) + (100×$2.501) | $583.70 |
Practical economics: building Chinese-language enterprise applications
Picture a document analysis SaaS that specializes in Chinese regulatory compliance and financial audits. It processes 400M input tokens and 100M summary tokens monthly (Workload C: $583.70 per month).
Say the product serves 50 corporate clients on a $200/month retainer ($10,000 monthly revenue). The underlying foundation model compute then accounts for less than 6% of revenue. That leaves a healthy 94%+ margin to fund development, sales, and infrastructure.
FAQ
Is Tencent Hunyuan really free to use? The weights are free to download and modify under Apache 2.0. But serving a 770B parameter model takes 512GB+ of high-speed GPU memory, so if you choose to self-host, you'll face significant ongoing hardware expenses.
At what scale does self-hosting Hy4 become cheaper than the hosted API? The hosted API bills at just $0.834/$2.501 per million tokens. Self-hosting only breaks even on sustained enterprise workloads exceeding tens of billions of tokens per month, with near-perfect hardware utilization.
How does Hy4 compare on price against competing Chinese flagships? At $0.834 input and $2.501 output, Hy4 is significantly less expensive than Kimi K3 ($3.00/$15.00) and Qwen3.8-Max ($2.00/$6.00). That makes it one of the most cost-effective pro-tier models available.
Is Hunyuan Hy4 licensed for commercial software? Yes. Tencent released Hy4 under the standard Apache 2.0 license, which permits unrestricted commercial deployment and fine-tuning.