Chinese AI Price War 2026: Real API Cost Across Ten Providers
The short answer
China's generative AI scene has changed what most of us think of as "affordable" token pricing. The catch is that you can't just glance at the headline input rate anymore and call it a day. Across ten major frontier labs, three things now decide what actually lands on your invoice: context caching discounts, time-of-day peak tariffs, and model generation efficiency.
Here's the quick version:
- The pricing spread across pro-tier models is huge. Take a high-volume monthly workload of 400M input and 100M output tokens with no caching. Flagship prices run from $261 per month on Xiaomi's MiMo-V2.5-Pro all the way up to $2,700 per month on Moonshot's Kimi K3, a 10x difference in software cost. If you're also weighing self-hosting, our MiMo API and self-hosting cost analysis goes deeper on that side of the math.
- Aggressive prompt caching reshuffles the leaderboard. Providers discount cached prompt tokens by 80% to 99%. With an 80% cache-hit rate, a 100M-in/20M-out agent workload on Xiaomi's flagship costs just $26.39 per month. That's cheaper than even standard un-cached flash models.
- Dynamic pricing means peak and off-peak rate cards. DeepSeek charges 2x higher rates during weekday daytime hours (8:00–22:00 UTC+8), while MiniMax doubles its token rate once input prompts exceed 512K tokens.
- Token rates are not task rates. Reasoning models emit "thinking tokens" that bill at pricey output rates. A cheaper per-token model that rambles for 3,000 reasoning tokens can easily cost more per user resolution than a concise model with a higher baseline rate.
1. The ten providers and their current models
Here's a snapshot of current pay-as-you-go developer rates across ten leading Chinese foundation model providers:
| Provider | Model used here | Input / cache hit / output ($ per 1M) | Context |
|---|---|---|---|
| Moonshot | Kimi K3 (international) | $3.00 / $0.30 / $15.00 | 1,048,576 |
| Alibaba | Qwen3.8-Max | $2.00 / $0.25 / $6.00 | 1M |
| Zhipu / Z.ai | GLM-5.3 | $1.40 / $0.26 / $4.40 | about 1M |
| DeepSeek | deepseek-v4-pro (V4-Pro-0813) | Peak $1.32 / $0.044 / $3.96; off-peak $0.66 / $0.022 / $1.98 | 1M |
| Tencent | Hy4 preview | $0.834 / $0.042 / $2.501 | 1M |
| Xiaomi | MiMo-V2.5-Pro | $0.435 / $0.0036 / $0.87 | 1M |
| MiniMax | MiniMax-M3 (up to 512K input) | $0.30 / $0.06 / $1.20 | Two price tiers (≤512K and >512K input) |
| StepFun | Step 3.7 Flash | $0.20 / $0.04 / $1.15 | 256K |
| Baidu | ERNIE 5.1 | Mainland only: ¥4 in / ¥18 out (up to 32K input); ¥6 / ¥22 (32K-128K) | 128K; excluded from USD tables |
| ByteDance | Doubao / Seed text model via BytePlus (international); see Doubao and Volcano Engine pricing for the access and regional-price caveats | Not available | Not confirmed |
For lightweight routing and high-frequency classification, these same labs also offer ultra-budget flash tiers: DeepSeek Flash ($0.15–$0.30 input / $0.60–$1.20 output), Zhipu GLM-5.3-Flash ($0.15 / $0.50), Xiaomi MiMo-V2.5 ($0.14 / $0.28), and StepFun Step 3.5 Flash ($0.10 / $0.30).
A few billing nuances worth keeping in mind:
- Moonshot Kimi K3: Priced closer to Claude Sonnet than to budget endpoints. It's aimed at multi-turn coding and massive document synthesis across its 1M context window.
- Alibaba Qwen: Qwen3.8-Max comes with stable enterprise pricing and automated context caching. Alibaba's console dynamically optimizes cache reuse for you.
- Tencent Hunyuan: Hunyuan Hy4 is an Apache 2.0 open-weight flagship at an aggressive $0.834 input rate.
- MiniMax: Advertises continuous 50% promotional discounts on M3, with distinct pricing tiers below and above 512K input tokens.
2. Real workloads
Rate cards only get interesting once you run real numbers through them. So we applied each provider's pricing to four common development scenarios:
- Workload A (Light interaction): 1M input + 250K output tokens.
- Workload B (Medium developer usage): 10M input + 3M output tokens.
- Workload C (High-volume monthly service): 400M input + 100M output tokens.
- Workload D (Cached agent pipeline): 100M input (with 80% cache hits) + 20M output tokens.
| Model | A: 1M in + 250K out | B: 10M in + 3M out | C: 400M in + 100M out (monthly) | D: 100M in, 80% cached + 20M out |
|---|---|---|---|---|
| Step 3.5 Flash | $0.175 | $1.90 | $70.00 | $9.60 |
| MiMo-V2.5 | $0.21 | $2.24 | $84.00 | $8.62 |
| GLM-5.3-Flash | $0.275 | $3.00 | $110.00 | $15.40 |
| DeepSeek V4.1-Flash, off-peak | $0.30 | $3.30 | $120.00 | $15.24 |
| Step 3.7 Flash | $0.4875 | $5.45 | $195.00 | $30.20 |
| MiniMax-M3 (≤512K) | $0.60 | $6.60 | $240.00 | $34.80 |
| DeepSeek V4.1-Flash, peak | $0.60 | $6.60 | $240.00 | $30.48 |
| MiMo-V2.5-Pro | $0.6525 | $6.96 | $261.00 | $26.39 |
| DeepSeek V4-Pro, off-peak | $1.155 | $12.54 | $462.00 | $54.56 |
| Tencent Hy4 preview | $1.459 | $15.84 | $583.70 | $70.06 |
| DeepSeek V4-Pro, peak | $2.31 | $25.08 | $924.00 | $109.12 |
| GLM-5.3 | $2.50 | $27.20 | $1,000.00 | $136.80 |
| Qwen3.8-Max | $3.50 | $38.00 | $1,400.00 | $180.00 |
| Kimi K3 (international) | $6.75 | $75.00 | $2,700.00 | $384.00 |
Workload D shows the power of caching nicely. Xiaomi's flagship MiMo-V2.5-Pro ($26.39) undercuts even efficient models like Step 3.7 Flash ($30.20), because its cache-hit tariff is discounted by over 99%.
3. The caching war
Prompt caching is where the real competition is happening among Chinese AI providers right now. Reusing system prompts, RAG document embeddings, and conversation histories cuts your billable tokens dramatically:
| Model | Cache hit ÷ cache miss |
|---|---|
| MiMo-V2.5-Pro | 0.8% |
| DeepSeek V4.1-Flash | 2.0% |
| MiMo-V2.5 | 2.0% |
| DeepSeek V4-Pro | 3.3% |
| Tencent Hy4 preview | 5.0% |
| Moonshot Kimi K3 | 10.0% |
| Alibaba Qwen3.8-Max | 12.5% |
| Zhipu GLM-5.3 | 18.6% |
| StepFun Step 3.7 Flash | 20.0% |
| MiniMax-M3 | 20.0% |
The gap here is wild. Xiaomi charges less than 1% of the baseline input rate for cached prefixes, while DeepSeek and Tencent sit around 2% to 5%. If your app keeps a consistent, large context prefix (an agent tool definition or an API specification, say), these deep cache discounts add up to serious savings.
4. Operational rules and rate structures
A few rules of the road that can quietly shape your bill:
- Peak vs off-peak scheduling: DeepSeek's 50% off-peak discount (22:00–8:00 Beijing Time) is a gift for asynchronous batch processing, backfill data labeling, and non-urgent report generation.
- Context length scaling: Kimi K3 and Qwen3.8-Max keep flat pricing across their 1M token windows, but MiniMax doubles its rate above 512K tokens. It's worth checking whether your provider uses multi-tier context pricing before you commit.
- Cache eviction policies: Prompt caches run on least-recently-used (LRU) memory pools. During high-traffic spikes, providers like StepFun note that cache entries may be cleared earlier than during quiet periods.
5. Cheap per token is not cheap per task
When you're benchmarking models, raw token price only tells half the story. The other half is how the model actually behaves when it generates:
- Reasoning token burn: Modern reasoning models produce a lot of hidden chain-of-thought tokens before they give you an answer. Output tokens cost 3x to 5x more than input tokens, so a model that generates 2,000 reasoning tokens per prompt can quickly wipe out its input-price advantage.
- Reasoning effort controls: Platforms like StepFun and DeepSeek let you tune reasoning effort (low, medium, high) or switch thinking off entirely for deterministic classification tasks.
- Trajectory efficiency: Different models solve agentic tasks in different numbers of tool calls. A model with sharp tool-calling that finishes in two turns is far cheaper in practice than a low-cost model that gets stuck in five-turn retry loops.
6. Build & Earn: a cost-routed AI support-agent product
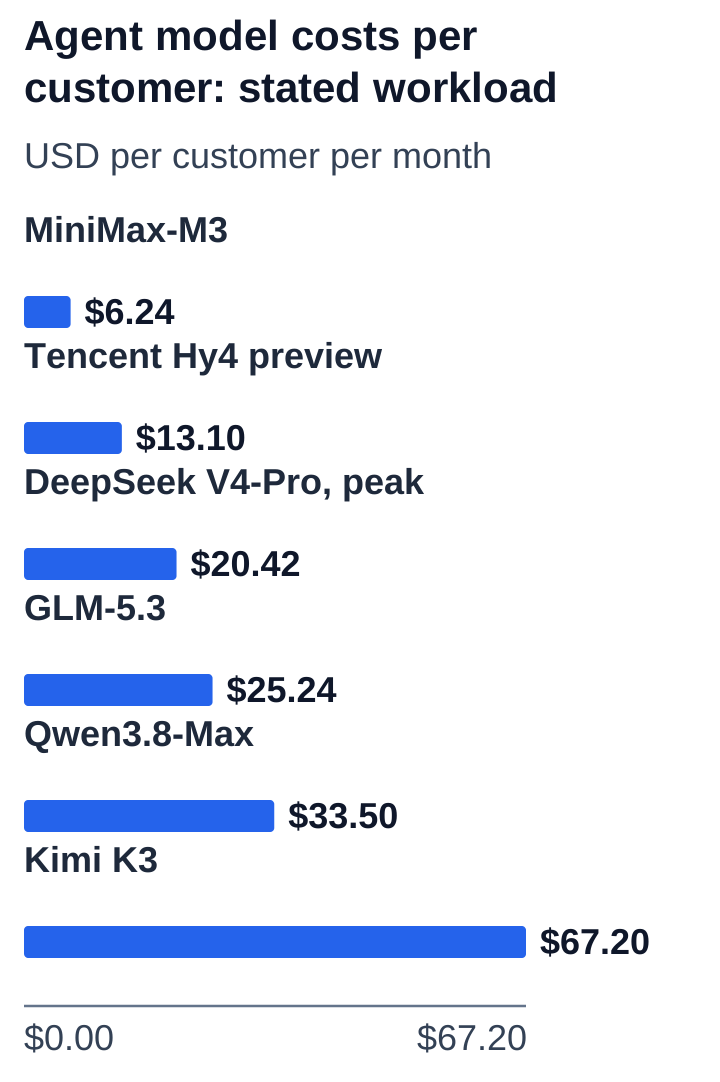
Let's see how this plays out for an actual business. Imagine an AI customer support SaaS charging $99 per customer per month. Each client account averages 20M input tokens (with a 70% cache hit rate) and 3M output tokens per month:
| Model | Model cost per customer | Model-cost share of $99 | Model-cost gross margin |
|---|---|---|---|
| Kimi K3 | $67.20 | 67.9% | 32.1% |
| Qwen3.8-Max | $33.50 | 33.8% | 66.2% |
| GLM-5.3 | $25.24 | 25.5% | 74.5% |
| DeepSeek V4-Pro, peak | $20.42 | 20.6% | 79.4% |
| Tencent Hy4 preview | $13.10 | 13.2% | 86.8% |
| DeepSeek V4-Pro, off-peak | $10.21 | 10.3% | 89.7% |
| MiniMax-M3 | $6.24 | 6.3% | 93.7% |
| MiMo-V2.5-Pro | $5.27 | 5.3% | 94.7% |
| DeepSeek V4.1-Flash, off-peak | $2.74 | 2.8% | 97.2% |
| Step 3.5 Flash | $1.78 | 1.8% | 98.2% |
Strategic Model Routing
Good product engineering rarely bets everything on one model. Add a routing layer that sends 85% of everyday conversational queries to an economical tier (such as DeepSeek Flash or MiMo-V2.5). Then escalate the remaining 15% of complex, multi-step reasoning queries to Kimi K3 or Qwen3.8-Max. A SaaS platform set up this way lands at an average model cost under $12 per customer (over 87% gross margin), and it still gets elite problem-solving accuracy where it counts.
7. Strategic takeaways for engineering leaders
- Design for cache stability: Put your invariant prompt pieces (system rules, tool schemas, brand knowledge) at the very start of your prompt array so cache hit rates stay high across user turns.
- Take advantage of time zones: If your users are in Europe or the Americas, scheduling batch workloads during Chinese nighttime hours automatically captures off-peak pricing on DeepSeek and regional providers.
- Audit output token volume: Keep an eye on your token analytics for runaway reasoning loops. Setting explicit
max_tokenslimits and tuning reasoning effort will save you from unpleasant billing surprises.