Kimi K3 vs DeepSeek vs Qwen 2026: Real API Cost
The bottom line: the idea of a single "cheap Chinese AI model" tier no longer holds up. With Moonshot's launch of Kimi K3, frontier pricing has split sharply across Beijing, Hangzhou, and Shanghai.
Kimi K3 sits at $3.00 per million input tokens and $15.00 per million output tokens. That is directly comparable to Anthropic's Claude Sonnet tier, not a budget endpoint. DeepSeek and Alibaba Cloud Qwen still keep their entry-level pricing aggressive. DeepSeek Flash runs at just $0.15 to $0.30 per million input tokens depending on the time of day, and Qwen Plus lists around $0.40 per million input tokens. The catch is that each provider's flagship reasoning model has moved upmarket: DeepSeek Pro reaches up to $1.32/M input at peak hours, and Qwen 3.8 Max sits at $2.00/M input. For model-specific workload assumptions, read the Kimi K3 workload and caching breakdown.
Here is how total cost compares across three normalized monthly production workloads:
| Workload | Kimi K3 | DeepSeek Flash (off-peak) | DeepSeek Pro (off-peak) | Qwen Plus (promo) | Qwen Max |
|---|---|---|---|---|---|
| 10M in + 2M out | $60.00 | $2.70 | $10.56 | $7.20 | $32.00 |
| 100M in + 20M out | $600.00 | $27.00 | $105.60 | $72.00 | $320.00 |
| 1B in + 200M out | $6,000.00 | $270.00 | $1,056.00 | $720.00 | $3,200.00 |
At every scale, Kimi K3 runs 20x to 22x higher than DeepSeek's cheapest Flash endpoint. That gap comes from different architectural goals, billing mechanics, and target workloads, so it isn't just a sticker-price quirk.
My practical rule of thumb: don't pick one model for everything. Pick the cheapest model that clears your quality bar for each job, and pay for the expensive one only where it earns its keep.
1. Current Model Lineups and API Mechanics
Kimi / Moonshot AI
Moonshot's developer platform builds its pricing around large-context caching:
| Model | Input (cache-miss) | Cached input | Output | Context |
|---|---|---|---|---|
| kimi-k3 | $3.00/M | $0.30/M (cache write: $3.00/M at 5-min TTL, $6.00/M at 1-hour TTL) | $15.00/M | 1,048,576 tokens |
| kimi-k2.7-code | $0.95/M | $0.19/M | $4.00/M | 262,144 tokens |
| kimi-k2.7-code-highspeed | $1.90/M | $0.38/M | $8.00/M | 262,144 tokens |
| kimi-k2.6 | $0.95/M | $0.16/M | $4.00/M | 262,144 tokens |
Kimi K3 runs with always-on internal reasoning. You can tune reasoning_effort (low, medium, max), but you can't turn the reasoning trajectories off entirely, and all thinking tokens bill at the full $15.00/M output rate. On the plus side, K3 supports a 1M context window with an automatic 90% cache discount ($0.30/M). That makes it economical for code analysis and long-document audits where the same context gets queried repeatedly.
DeepSeek
DeepSeek bases its billing on server load scheduling and off-peak incentives:
| Model | Input, cache-hit | Input, cache-miss | Output | Context |
|---|---|---|---|---|
| deepseek-flash (DeepSeek-V4.1-Flash) | off-peak $0.003 / peak $0.006 | off-peak $0.15 / peak $0.30 | off-peak $0.60 / peak $1.20 | 1M tokens, 384K max output |
| deepseek-v4-pro (DeepSeek-V4-Pro-0813) | off-peak $0.022 / peak $0.044 | off-peak $0.66 / peak $1.32 | off-peak $1.98 / peak $3.96 | 1M tokens, 384K max output |
DeepSeek uses a strict time-of-day tariff. Peak hours run from 01:00–04:00 and 06:00–10:00 UTC Monday through Friday. All other hours, including entire weekends and Chinese public holidays, are billed at a 50% discount. Prompt cache hits get a 98% discount on input tokens ($0.003/M off-peak), which sets the lowest cost floor in the global market.
Qwen / Alibaba Cloud Model Studio
Alibaba Cloud's Model Studio offers multi-region availability and tiered token pricing:
| Model | Input (≤ first tier) | Output (≤ first tier) | Notes |
|---|---|---|---|
| qwen3.8-max | $2.00/M | $6.00/M | Flat across full 1M context (no tiering) |
| qwen3.7-max | $2.50/M | $7.50/M | Flat across full 1M context |
| qwen-max (legacy, non-thinking only) | $1.60/M | $6.40/M | No tiered pricing |
| qwen3.7-plus | $0.40/M (0–256K) → $1.20/M (256K–1M) | $1.60/M (0–256K) → $4.80/M (256K–1M) | Tiered pricing based on input length |
| qwen-plus (current alias) | $0.40/M (0–256K) → $1.20/M (256K–1M) | $1.20/M non-thinking, $4.00/M thinking (0–256K) | Thinking and non-thinking output billed differently |
The practical catch with Qwen is that rates vary by cloud data center region. Deployments in Singapore or international regions give you global access with an initial 1M free token quota. Chinese domestic regions (Beijing, Shanghai) have their own local rates and night-time discounts. On tiered models, crossing an input threshold (for example, beyond 256K tokens) raises the per-token rate across the entire request.
2. Normalized Workload Cost (CALCULATION)
To compare budgets side by side, here is each lab's active models across three monthly volume tiers, without any cache discounts applied:
| Workload | Kimi K3 | Kimi K2.7 Code | DeepSeek Flash (off-peak) | DeepSeek Flash (peak) | DeepSeek Pro (off-peak) | Qwen Plus (Singapore, captured display rate) | Qwen Max (Singapore) |
|---|---|---|---|---|---|---|---|
| 10M in + 2M out | $60.00 | $17.50 | $2.70 | $5.40 | $10.56 | $7.20 | $32.00 |
| 100M in + 20M out | $600.00 | $175.00 | $27.00 | $54.00 | $105.60 | $72.00 | $320.00 |
| 1B in + 200M out | $6,000.00 | $1,750.00 | $270.00 | $540.00 | $1,056.00 | $720.00 | $3,200.00 |
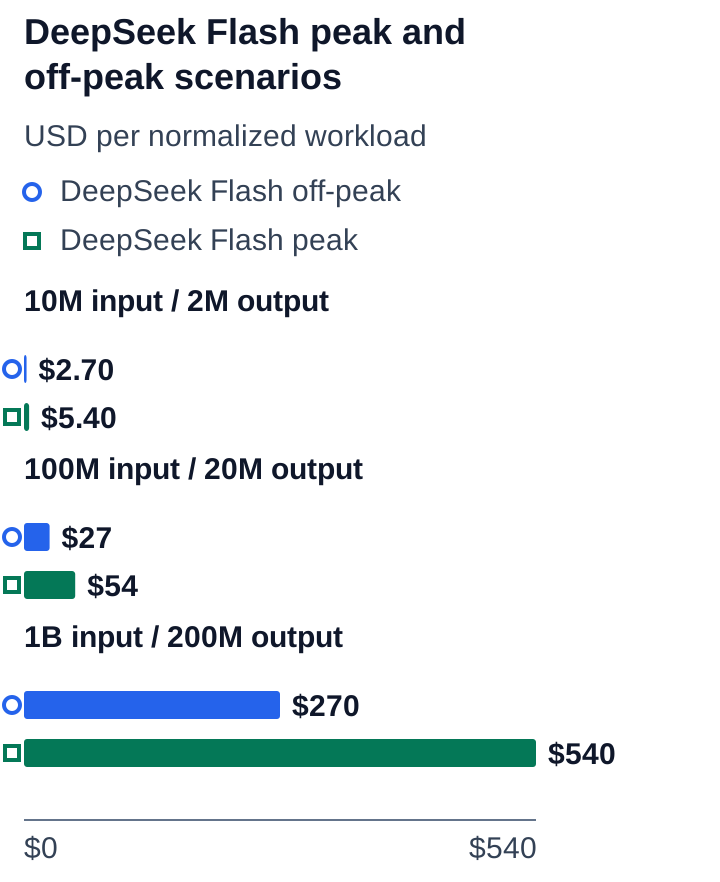
With prompt caching active, effective input costs drop significantly on all three platforms. DeepSeek offers up to 98% cache-hit savings, Kimi provides a 90% discount, and Qwen delivers 80% to 90% depending on the model. For multi-turn agent workflows with steady prompt prefixes, effective input costs often fall by 60% to 80%.
In real-world production, that means caching can matter more than the model you pick. If your prompts share a stable prefix, design for cache hits first and compare list prices second.
3. Hidden Costs and Structural Risk
When you build production systems on these endpoints, a few architectural details can quietly move your monthly bill:
- Kimi K3's reasoning token overhead: K3 uses mandatory chain-of-thought processing, so reasoning tokens are billable output ($15.00/M). In multi-turn agents where reasoning chains get returned in conversation history, generation fees can quietly dominate your invoice unless you bound your prompts carefully.
- DeepSeek's time-of-day windowing: Workloads that run during peak UTC windows pay exactly double the off-peak token price. Asynchronous batch jobs (data ingestion, document processing, vector indexing) are easy wins for off-peak scheduling.
- Qwen's multi-region pricing variation: The same Qwen model identifier deployed in Frankfurt or Virginia can bill at 2x to 3x the rate of domestic Chinese or Singapore endpoints. Double-check the region identifier in your API client configuration. It's a very easy line to overlook.
- Input tier step-ups: On tiered Qwen models, a 260K token request bills the entire input payload at the higher tier ($1.20/M instead of $0.40/M). Splitting prompts to stay under threshold boundaries avoids surprise spikes.
4. Commercial and Regional Access
All three providers support commercial API access for international businesses:
- DeepSeek: Direct international billing with global credit card support. Infrastructure is hosted in China, which your engineering team should weigh against internal compliance policies.
- Qwen (Alibaba Cloud): Broad global availability across Singapore, Germany, the US, and Japan. International developers can deploy via Singapore endpoints for standard enterprise compliance, SOC 2 alignment, and local payment processing.
- Kimi / Moonshot AI: Accessible directly with USD card top-ups, and now deployable within the US on Amazon Bedrock with strict virtual private cloud isolation.
5. Build & Earn Scenario: A Document-Summarization API Wrapper
Picture an enterprise document processing service charging $0.02 per summarized document (averaging 3,000 input tokens and 300 output tokens per document), processing 500,000 documents monthly ($10,000 monthly gross revenue, representing 1.5B input and 150M output tokens):
| Route | Token cost (CALCULATION) | Share of $10,000 | Model-cost gross margin |
|---|---|---|---|
| DeepSeek Flash, off-peak | 1,500×$0.15 + 150×$0.60 = $315.00 | 3.2% | 96.8% |
| Qwen Plus, Singapore captured display rate | 1,500×$0.40 + 150×$1.60 = $840.00 | 8.4% | 91.6% |
| Kimi K2.7 Code | 1,500×$0.95 + 150×$4.00 = $2,025.00 | 20.3% | 79.7% |
| Kimi K3 | 1,500×$3.00 + 150×$15.00 = $6,750.00 | 67.5% | 32.5% |
At scale, your model choice decides whether the product is profitable. DeepSeek Flash yields a 96.8% model-level gross margin ($315 token cost). Running Kimi K3 on the exact same workload eats over 67% of gross revenue ($6,750 token cost). For production apps, the pattern I'd reach for is intelligent routing: send high-volume extraction to DeepSeek Flash or Qwen Plus, and save Kimi K3 for complex reasoning and audit tasks. If summarization is the whole product, K3 is hard to justify. If it's the escalation path for the tricky 5% of documents, it's a sensible spend.
FAQ
Is Kimi K3 still considered a budget model? No. At $3.00/M input and $15.00/M output, Kimi K3 is priced in line with frontier models like Claude Sonnet. It's built for complex reasoning and 1M context processing, not high-volume budget extraction.
Which endpoint is cheapest for high-volume batch processing? DeepSeek Flash during off-peak hours has the lowest cost floor in the market ($0.15/M input, $0.60/M output, and $0.003/M cache hits). That makes it a very good fit for non-interactive data pipelines.
Does Qwen charge different rates by region? Yes. Alibaba Cloud Model Studio applies region-specific rate cards. Singapore endpoints are the standard international baseline, while domestic Chinese regions offer separate nighttime discounts.
Can these models be self-hosted? Kimi K3 and several Qwen checkpoints provide open weights. Production self-hosting, though, needs substantial enterprise GPU infrastructure (typically 8 to 16 modern high-VRAM accelerators), so hosted APIs are far more cost-effective for most engineering teams.