OpenAI Web Search vs Gemini Grounding vs Perplexity Sonar: Real Grounded AI Search Cost per 100,000 Queries in 2026
The bottom line: Perplexity Sonar is the only one of the three built around web search from the ground up, and it shows in the price. At 100,000 queries, Sonar's base model costs about $600 total (a $5-per-1,000-query search fee plus a small token charge), while Sonar Pro costs about $1,400 for the same volume, with a more capable model and deeper search.
This comparison covers model answers grounded in web search. For retrieved results passed to your own pipeline, compare search API billing. Tavily vs Exa vs Perplexity Sonar API: Real AI Web Search Cost per 100,000 Queries in 2026.
The catch is that the other two aren't quite apples-to-apples. OpenAI's web search tool, bolted onto its Responses API, costs $1,000 in tool-call fees alone at $10 per 1,000 calls, and that's before the separate, variable token cost of the underlying model call and the search-result content it has to process. Google's Gemini grounding with Google Search is the most expensive of the three at this volume: at $35 per 1,000 requests beyond a 1,500-per-day free allowance, 100,000 monthly queries (averaging above that daily free threshold) costs roughly $1,925 in grounding fees alone.
My practical rule of thumb: if you're running steady, high-volume search-backed answers, start your cost model with Sonar and make the other two prove they're worth the premium. If your traffic is low and smooth, Gemini's free tier can quietly win. Read on for why.
What each vendor bills
OpenAI Web Search tool — billing checked 27 October 2026. The official OpenAI API rate card lists $10 per 1,000 calls for web_search, with retrieved search-content tokens billed at the chosen model's rates. The OpenAI row below uses this tool. At 100,000 billable tool calls, its tool fee is $1,000, before model-token charges.
The same rate card lists $25 per 1,000 calls for web_search_preview with non-reasoning models, with search-content tokens free. That produces a $2,500 tool fee at 100,000 calls, and ordinary input and output tokens still add to the bill. Preview search with reasoning models instead lists $10 per 1,000 calls plus search-content tokens. These are different billing paths, so $25 is not automatically a stale or conflicting quote. Confirm the exact tool and supported model, then count tool calls rather than assuming one call per user question. This OpenAI billing correction does not re-verify the Gemini and Sonar scenario figures below.
Gemini grounding with Google Search (OFFICIAL, confirmed directly by Google Cloud Billing support on Google's own developer forum). You get 1,500 free grounding requests per day, then $35 per 1,000 requests beyond that daily allowance. Billing is proportional rather than rounded up to a minimum unit. Google's own support response confirms that 10 requests over the free tier bills $0.35, not a flat $35 minimum charge. Each API call using the google_search tool counts as one billable grounding request, even if the model performs multiple underlying search queries to answer one response. From a billing perspective, a single expensive multi-search response costs the same as a single cheap one-search response.
Perplexity Sonar API (OFFICIAL, Perplexity's own pricing documentation). Billing comes in two parts: token cost plus a separate per-request search fee. Sonar (base model): $1 per million input tokens, $1 per million output tokens, plus $5 per 1,000 searches. Sonar Pro: $3 per million input, $15 per million output, plus $5 per 1,000 searches. Independent analysis notes that Sonar, Sonar Pro, and Sonar Reasoning Pro all carry this separate per-request search fee, ranging $5 to $14 per 1,000 requests depending on model and search depth.
On a short query, this flat search fee routinely outweighs the token cost several times over, which makes the per-request fee, not the token rate, the dominant cost driver for most realistic query lengths.
Cost per 100,000 queries
Formula: OpenAI = (queries ÷ 1,000) × $10, tool-call fee only, excluding the separate model token cost; Gemini = max(0, (queries ÷ 30 days − 1,500 free/day)) × 30 ÷ 1,000 × $35, assuming usage is spread evenly across the month; Perplexity = (queries ÷ 1,000) × $5 search fee + token cost at an ILLUSTRATIVE 500 input / 500 output tokens per query.
| Platform | Basis | Cost at 100,000 queries/month |
|---|---|---|
| OpenAI Web Search (tool-call fee only) | $10/1,000 calls | $1,000 |
| Perplexity Sonar (base) | $5/1,000 search fee + token cost | $600 |
| Perplexity Sonar Pro | $5/1,000 search fee + token cost (higher-rate model) | $1,400 |
| Gemini grounding | $35/1,000 beyond 1,500/day free allowance | $1,925 |
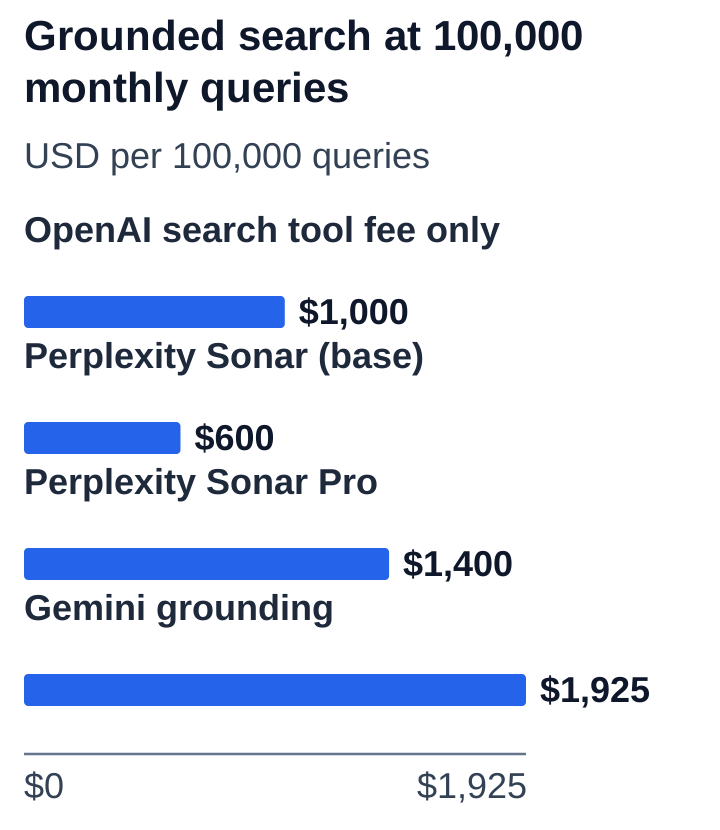
At this specific volume (100,000 queries spread evenly over a month, averaging above Gemini's 1,500/day free threshold), Perplexity Sonar base is the cheapest option, OpenAI's tool-call fee alone sits in the middle (before its own token cost goes on top), and Gemini is the most expensive. That said, Gemini's daily free allowance means a genuinely lower-volume workload that stays under 1,500/day on every single day could cost nothing at all, a structural advantage that neither of the other two options offers.
What OpenAI's and Gemini's figures leave out
Neither OpenAI's $10-per-1,000-call fee nor Gemini's $35-per-1,000-request fee includes the underlying model's own token cost. Both are bolt-on tool fees charged in addition to a separate, normal LLM API call. Perplexity's Sonar models are the only ones of the three where the search fee and the token cost are both native, published parts of one unified rate card for the same product. So comparing Perplexity's all-in total directly against OpenAI's or Gemini's tool-fee-only figures understates the true cost of the latter two, unless you add their respective model token costs back in.
When OpenAI's model invokes the web_search tool, it ingests the scraped search snippets into its context window, which generates billable input tokens at the base model's standard rates. If your prompt triggers three external searches to synthesize an answer, that single prompt bills $0.03 in tool fees plus the input and output tokens for the entire multi-step chain. For Gemini, Google absorbs the token overhead of internal search lookups within the flat grounding fee, but your application still pays for the user prompt and the final generated output tokens under standard Gemini 1.5 or 2.0 Flash / Pro rates.
In real-world production, this is the part that bites people: the tool fee is the number on the pricing page, but the token bill is the number on the invoice. Run a small pilot with your actual prompts before you trust any spreadsheet, including this one.
The free-tier threshold on Gemini
Formula: daily free requests = 1,500; proportional overage billing above that, per day. A workload that stays under 1,500 grounding requests on every single day, up to about 45,000 a month evenly spread, pays nothing at all for grounding on Gemini. The free allowance resets daily and does not roll over or accumulate into a monthly pool, so evenly distributing a fixed monthly total across every day maximizes how much of it is captured by the free tier. At 100,000 queries spread evenly (about 3,333/day), every day uses its full 1,500-request allowance before any billing starts, leaving 1,833/day billable.
A bursty traffic pattern does significantly worse under this daily structure. If your application handles 10,000 grounded queries on Monday and stays quiet for the rest of the week, Monday consumes its 1,500 free requests and bills 8,500 requests at $35 per 1,000 ($297.50). The quiet days provide zero rollover benefit, and their daily 1,500 allowances evaporate unused. Spreading that same 10,000 weekly queries evenly across seven days (roughly 1,428 queries per day) would keep every single day below the 1,500 threshold, reducing your grounding fee from nearly $300 to exactly $0.00.
If your workload is batchable or queueable, a little rate-smoothing code is some of the cheapest engineering you'll ever do.
Sensitivity
- Query length and token consumption. This directly scales Perplexity's token bill and the underlying LLM charges on OpenAI and Gemini. A deep research agent retrieving long-form articles will accumulate substantial token charges on all three platforms, whereas a quick factual lookup is dominated by the fixed search fee.
- Daily usage pattern on Gemini. A workload that can smooth or queue its requests to stay under 1,500 queries per calendar day avoids grounding fees entirely. Front-loaded spikes push volume past the daily threshold into full $35/1,000 billing.
- Which Perplexity model tier you select. Sonar Pro's fixed search fee is identical to base Sonar's ($5/1,000), but its token rates are 3x higher on input ($3.00/M vs $1.00/M) and 15x higher on output ($15.00/M vs $1.00/M). The model tier, rather than the search request count, drives the bill.
- Which OpenAI search tool and model you invoke. The production
web_searchtool ($10/1,000 calls) and non-reasoningweb_search_preview($25/1,000 calls) use fundamentally different billing mechanics for retrieved search tokens. Compare your projected query volume across the exact tool configuration you plan to deploy.
Budgeting traps
- Pricing OpenAI's or Gemini's grounded search off the tool-call fee alone. Both platforms charge normal LLM token fees on top of the search fee. Comparing OpenAI's $1,000 tool fee against Perplexity's $600 all-in total creates a false comparison unless you add model tokens back to OpenAI.
- Concentrating Gemini usage into bursty, high-volume days instead of spreading it evenly. Because the daily free allowance does not roll over, bunching queries into fewer days wastes unused free quota on quiet days and inflates your total billable request count.
- Assuming Perplexity's $5-per-1,000 search fee applies to every Sonar tier. Sonar Reasoning Pro and deeper multi-step search modes carry fees up to $14 per 1,000 requests, nearly triple the entry-level search surcharge.
- Treating OpenAI's $10 and $25 call fees as contradictory quotes. Both appear on the official rate card for different tool/model paths. Applying the $10
web_searchrate to non-reasoning preview calls understates the tool fee by $1,500 at 100,000 calls, before accounting for their different search-content token charges.
What to ask before you buy
For OpenAI, confirm the exact tool name, supported model, number of billable search calls and treatment of retrieved content. Use the official web-search guide to check tool support. Add normal model-token charges and any billed search-content tokens to the tool fee. Model Gemini's full cost with its applicable grounding and model-token charges too. Perplexity's illustrated Sonar total is not directly comparable to either vendor's partial figure.
My honest take: if you're at steady volume well above Gemini's free threshold and you just want grounded answers without a surprise invoice, Sonar's single rate card is the easiest to reason about. If you're already deep in the OpenAI or Google ecosystem, the premium may be worth it for the integration alone. Just price it with the tokens included before you commit.