AWS Bedrock vs Azure AI Foundry vs Google Vertex AI: Real Managed LLM Platform Cost per 1 Billion Tokens in 2026
The bottom line: the "cloud markup" story isn't one number. It depends on whether you're running a proprietary model (OpenAI, Anthropic) or an open-weight one. For Claude, there's effectively no markup at all. Anthropic's own documentation describes Google Cloud as a "partner-operated" platform that prices to match Anthropic's direct API dollar for dollar, and AWS Bedrock does the same for Claude. At 1 billion tokens (5:1 ratio), Claude Sonnet 5 costs $5,000 whether you reach it through Bedrock, Vertex AI, or Anthropic's own API directly.
For open-weight models, the managed-platform tax is real and large. Llama 3.3 70B costs $880 per billion tokens on Together AI, but the identical weights cost $1,364 on Google Vertex AI (a 55% premium) and $2,649 on AWS Bedrock (a roughly 201% premium). Same model, very different invoice.
The catch is that token rates are only part of the bill. Independent cost analyses report that real production bills on AWS Bedrock run 1.5 to 2 times the initial token-based estimate once Knowledge Bases, Agents, and Guardrails are added.
My practical rule of thumb: if you're mostly on Claude, pick your cloud for governance and commit-spend reasons, not price. If you lean on open-weight models, treat the hyperscaler premium as a deliberate line item, not a surprise.
Claude: no markup, but a recent repricing
If your architecture relies on Anthropic's Claude, you don't pay a platform penalty on either major cloud. Anthropic treats Google Cloud Vertex AI and AWS Bedrock as first-party partner platforms whose token rates mirror Anthropic's direct API rates dollar for dollar.
Under standard commercial pricing, Claude 3.5 Sonnet and Sonnet 5 run at $3.00 input and $15.00 output per million tokens across all three environments (Anthropic direct, AWS Bedrock, and Google Vertex AI). If you're working from an older pricing sheet, you may remember the introductory rate of $2.00 input / $10.00 output. That expired in August 2026, so current production budgets should use the post-promotional $3/$15 rate. Meanwhile, the flagship Claude Opus 4.8 sits at $5.00 input and $25.00 output per million tokens across Bedrock, Vertex AI, and direct API calls alike.
Since token pricing is identical across these surfaces, the real decision rarely comes down to model rates. Teams pick Bedrock or Vertex AI to make use of existing enterprise cloud commits (AWS EDP or Google Cloud Commitments), enforce IAM role-based access, and keep data governance inside private VPC subnets without routing payloads through third-party SaaS endpoints. Those are good reasons, and they're the ones worth weighing.
Open-weight models: the real, model-specific markup
Proprietary frontier models carry zero cloud premium, but open-weight models tell a very different story. Running community weights like Llama 3.3 70B on the hyperscalers brings steep markups compared with dedicated inference providers:
- Together AI (Dedicated Inference): Billed at roughly $0.88 per million tokens ($880 per billion tokens).
- Google Vertex AI Model Garden: Billed at $1.36 per million tokens ($1,364 per billion tokens), a 55% premium for running the identical model weights.
- AWS Bedrock: Billed at approximately $2.65 per million tokens ($2,649 per billion tokens), a 201% premium, which is more than triple the cost of dedicated inference.
To be fair about what you're paying for: this markup doesn't buy better model accuracy or lower latency. It covers fully managed cloud plumbing, unified enterprise billing, CloudWatch monitoring, and single-pane IAM access across hundreds of Foundation Models. For some organizations that's worth it, as long as you go in knowing the price.
In the Microsoft ecosystem, Azure AI Foundry takes a split approach. For small, high-frequency workloads, Phi-4-mini runs at approximately $0.07 input and $0.23 output per million tokens (~$97 per billion tokens at a 5:1 ratio). That's a dramatic 35x to 40x cost reduction compared to frontier models, which makes it a great fit for classification, metadata tagging, or query routing. For heavier reasoning, Azure's GPT-4.1-class models bill at $2.00 input and $8.00 output per million tokens ($3,000 per billion tokens) with expanded 1-million-token context windows.
Cost per 1 billion tokens (5:1 input:output ratio)
Formula: cost per 1B = (5 × input rate + output rate) ÷ 6 × 1,000.
| Model tier | Platform | Cost per 1B tokens |
|---|---|---|
| Claude Sonnet 5 (current rate) | Bedrock, Vertex AI, or Anthropic direct — identical | $5,000 |
| Azure GPT-4.1-class | Azure AI Foundry | $3,000 |
| Llama 3.3 70B | AWS Bedrock | $2,649 |
| Llama 3.3 70B | Google Vertex AI | $1,364 |
| Llama 3.3 70B | Together AI (dedicated inference, for reference) | $880 |
| Azure Phi-4-mini | Azure AI Foundry | $97 |
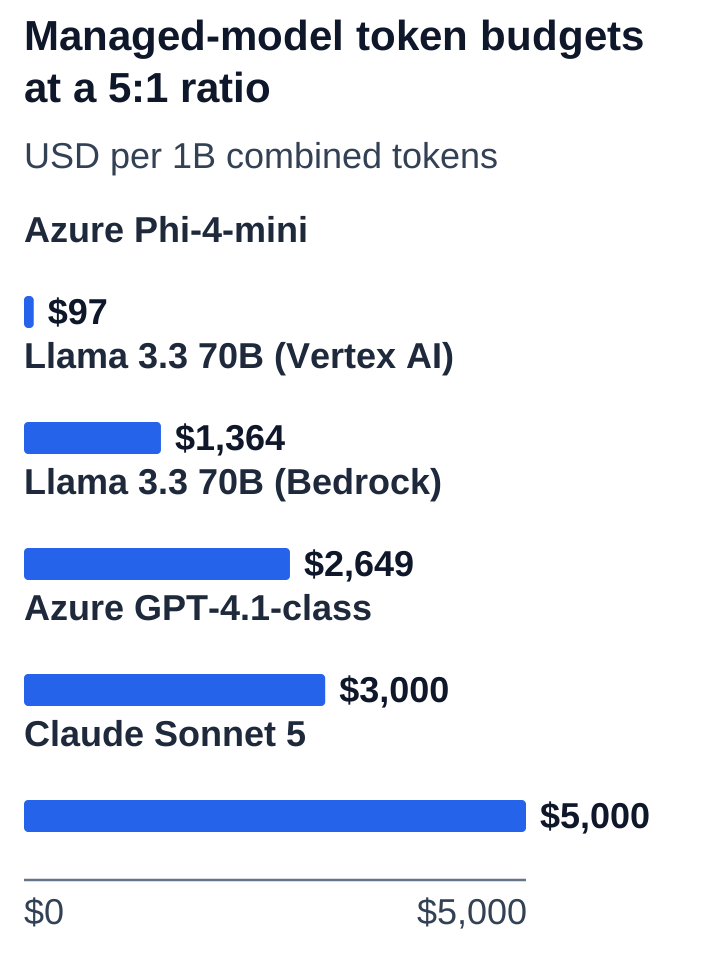
The absolute dollar gap between a frontier-tier model and Phi-4-mini widens as usage grows, not narrows, since both scale linearly with volume on their respective per-token rates.
What the token rate leaves out
FinOps practitioners who review enterprise AI bills consistently report that real-world invoices on AWS Bedrock and comparable cloud platforms run 1.5 to 2 times higher than the initial token math. The main cost drivers outside the model rate card:
- Persistent Vector Retrieval Infrastructure: Connecting Bedrock Knowledge Bases provisions underlying vector engines like OpenSearch Serverless. OpenSearch Serverless bills on OpenSearch Compute Units (OCUs) with minimum cluster baselines (often 2 to 4 OCUs running 24/7). That creates a static monthly overhead of $350 to $700+ before a single user query is answered.
- Multi-Turn Agent Overhead: Bedrock Agents and Azure AI Agents introduce autonomous reasoning loops. Each intermediate tool call, plan validation step, and memory retrieval appends tokens to the prompt context, frequently turning a single user question into 3x to 5x more billed tokens than a single-turn completion.
- Safety and Compliance Guardrails: Layering on AWS Bedrock Guardrails or Azure AI Content Safety adds a dedicated fee of $0.75 to $1.50 per 1,000 text units. Guardrails evaluate both input prompts and output generations, so inspection volume doubles on every request.
- VPC Endpoints and PrivateLink: Routing traffic privately through internal enterprise networks incurs AWS PrivateLink hourly interface fees and data transfer charges across Availability Zones.
In real production, this is usually where the budget conversation gets awkward. The model rate card is the easy part to forecast; the always-on infrastructure around it is what tends to surprise people.
Sensitivity
- Proprietary vs. Open-Weight Model Mix: If 90% of your production traffic runs on Claude, choosing between Bedrock, Vertex AI, or direct Anthropic has zero impact on token spend. If your architecture leans heavily on Llama 3.3 70B, running it on Bedrock instead of Together AI triples your monthly inference bill.
- Single-Turn Prompts vs. Agentic Chains: Direct stateless inference closely tracks the unit table. Stateful agents running multi-step tool calls compound token volume quickly, pushing the effective bill toward the 2x multiplier range.
- Traffic Volume vs. Fixed Baseline Costs: Low-traffic internal tools suffer disproportionately from fixed vector storage baselines (OpenSearch Serverless). High-volume customer-facing apps easily absorb the fixed storage costs, but they feel every cent of the hyperscaler per-token premium on open-weight models.
Budgeting traps
- Assuming open-source models are always cheap on hyperscalers: Running Llama 3.3 70B on AWS Bedrock costs $2,649 per billion tokens, which is uncomfortably close to proprietary frontier-class pricing like Azure's GPT-4.1 tier ($3,000 per billion).
- Overlooking 24/7 auxiliary service baselines: Spinning up a Knowledge Base without checking minimum OCU requirements can quietly generate thousands of dollars in annual idle compute costs.
- Budgeting against expired introductory rates: Calculating Claude Sonnet workloads at the former promotional $2/$10 rate leaves you with a surprise 50% budget shortfall once standard $3/$15 production invoices arrive.
- Treating the hyperscaler convenience tax as invisible: Paying a 201% premium for open-weight models on Bedrock can be perfectly justifiable if strict enterprise security compliance demands it. It just should be an explicit architectural choice rather than something you discover on the monthly invoice.
What to ask before you buy
Can your architecture route open-weight inference through specialized providers (such as Together AI, Fireworks, or Groq) using private networking, or does enterprise infosec strictly require hosting inside your primary AWS or GCP tenant? What's the non-negotiable monthly baseline cost for vector storage, search indexes, and agent orchestration before user traffic even arrives? And does your organization hold an Enterprise Discount Program (EDP) or cloud commitment that offsets the headline managed platform rates?
If you can answer those three honestly, you'll know more about your real cost per billion tokens than any pricing page can tell you.