OpenAI Realtime API vs Gemini Live API vs Deepgram Voice Agent API: Real Voice AI Cost per 10,000 Minutes in 2026
Shipping a low-latency voice agent means juggling three things at once: streaming audio token economics, how long your WebSocket connections live, and how smart the model behind the mic needs to be. The three vendors handle billing very differently. OpenAI bills in multimodal audio tokens and offers dramatic prompt caching discounts. Google Gemini Live charges per-minute streaming rates and meters silence as if it were speech. Deepgram bundles the whole audio pipeline into one flat rate ($4.50/hour).
At a typical commercial workload of 10,000 conversation minutes, total expenses range from $180 on Gemini Live native audio to $750 on Deepgram, and $773 to $1,152 on OpenAI Realtime. Here's how the three compare in November 2026.
My practical rule of thumb: the cheapest sticker price rarely survives contact with production. Session design (caching, silence handling, telephony) usually moves your bill more than the vendor logo does.
1. Architectural Approaches: End-to-End Multimodal vs Cascaded Pipelines
Conversational voice AI tends to follow one of two designs:
- End-to-End Multimodal Speech (OpenAI Realtime & Google Gemini Live): Audio goes straight into the neural network, and streamable audio comes back out over WebSockets or WebRTC. There's no intermediate text transcription step, so you keep human inflections, emotional cadence, interruptions, and sub-350ms latency.
- Cascaded Voice Agent Pipelines (Deepgram Voice Agent API): This bundles industry-leading Speech-to-Text (Nova-3), an external LLM (Llama 3.3 or GPT-4o mini), and low-latency Text-to-Speech (Aura) under one orchestration layer. Because STT, inference, and TTS are decoupled, you get full control over system prompts and tool calling at a predictable flat rate ($0.075/min).
2. Token Rates and Converting Audio Stream Time to Minutes
Audio waveforms don't come with tidy punctuation, so both OpenAI and Google meter speech in streaming audio tokens. At standard 24kHz conversational cadence, active speech averages approximately 1,200 audio tokens per minute:
- OpenAI Realtime API (gpt-realtime-2.1): Audio input costs $32.00 per million tokens ($0.0384/min), and audio output costs $64.00 per million tokens ($0.0768/min). The good news is that cached system prompts drop to $0.40/1M tokens, an 80x discount. That makes structured session caching the single most impactful cost lever you have.
- Google Gemini Live (Gemini 2.0 Flash / Live Native): Text input is $0.50/1M tokens, audio/video input is $3.00/1M tokens, and audio output is $12.00/1M tokens. That works out to a blended baseline of ~$0.018 per minute.
- Deepgram Voice Agent API: Billed at a predictable bundled rate of $4.50 per hour ($0.075/min), no matter the token counts. The practical catch: phone calls need telephony transport (e.g. Twilio or Telnyx SIP trunking), which adds approximately $0.014/min.
Cost per 10,000 minutes
Formula: cost = minutes × 1,200 tokens/minute × (input rate + output rate) ÷ 1,000,000, treating input and output as occurring symmetrically across a live session (both directions of audio flow continuously during a call).
| Platform / tier | Per-minute cost | Cost per 10,000 minutes |
|---|---|---|
| Gemini Live 2.5 Flash preview (older tier) | $0.00276 | $27.60 |
| Gemini Live, current native-audio rate | $0.018 | $180.00 |
| Gemini 3.8 Live (separately listed rate) | $0.0063 | $63.00 |
| Deepgram Voice Agent API (bundled STT+LLM+TTS) | $0.075 | $750.00 |
| OpenAI Realtime, gpt-realtime-2.1, cached | $0.077 | $772.80 |
| OpenAI Realtime, gpt-realtime-2.1, uncached | $0.115 | $1,152.00 |
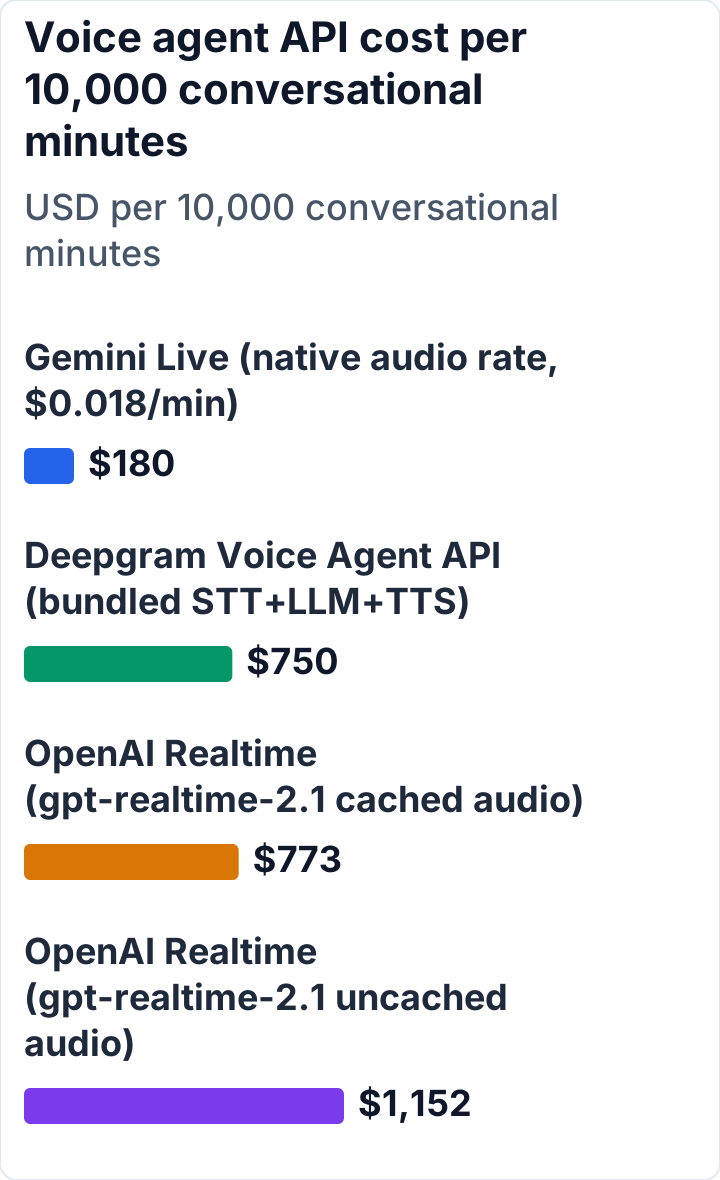
Notice how close Deepgram and cached OpenAI sit to each other. Once caching is working, the decision shifts from "which is cheaper" to "which experience and architecture do I actually want."
3. The OpenAI Caching Trap: Why Session Architecture Dictates Cost
On the OpenAI Realtime API, skipping prompt caching is the fastest way to watch a voice agent bill balloon. Every turn in a voice session references the persona instructions and earlier tool outputs, so an uncached 10-turn call re-bills the system prompt ten times at full price ($32/1M tokens). Once system prompts pass 1,500 tokens, uncached voice agents frequently surge past $0.30 to $0.45 per minute. Structure the WebSocket payload to maximize cache prefix hits, and costs stay anchored near $0.077/minute.
In real-world production, this means caching isn't a nice optimization to get to later. It should be on your launch checklist, right next to "does the microphone work."
4. Google Gemini Live and the "Dead Air" Metering Rule
Here's the one that surprises people: Gemini Live bills for silence. Google Cloud Billing treats an open WebRTC audio stream as continuous input compute, so dead air and customer hold times consume audio input tokens at the same rate as active speaking. If you run inbound support lines with long hold durations, it's worth implementing client-side Voice Activity Detection (VAD) to mute or suspend the streaming connection during idle periods. Otherwise you may end up paying for a very expensive moment of hold music.
Interactive Voice Agent Cost Simulator
Want the exact monthly budget for your call center or outbound voice bot, based on monthly minutes, telephony carrier rates, and speech synthesis models?
- Compare your projected call volume on our Interactive Voice Agent Decision Simulator to evaluate OpenAI, Gemini Live, Deepgram, Vapi, and Retell AI side by side.
Production Recommendation for Voice Engineers
- For Customer Support Call Centers (High Predictability): Go with Deepgram Voice Agent API ($0.075/min). The bundled pricing takes token anxiety off the table, and decoupled STT/TTS lets you swap LLM backends without touching your telephony pipeline.
- For Complex Reasoning & Emotional Human Nuance: Use OpenAI Realtime API (with Prompt Caching). If dynamic interruptions, conversational warmth, and fast tool calling are mission-critical, OpenAI delivers the most polished user experience at ~$0.08/min.
- For High-Volume, Budget-Constrained Mobile Apps: Try Gemini Live Native Audio. At ~$0.018/min, Google offers unbeatable economics for in-app voice assistants, as long as your client properly manages stream suspension during silence.
If you're still torn, my two cents: pick based on how much your callers will notice the difference. If conversation quality is the product, pay for it. If the voice agent is a utility, save your budget and take the predictable option.