Firecrawl vs Jina AI Reader vs Diffbot: Real Web Extraction Cost per 1 Million Pages in 2026
The short answer: the three price extraction in fundamentally different units, and the harder the page mix, the more that difference matters. Firecrawl and Diffbot charge a fixed number of credits per page (with more credits for tougher extraction); Jina AI Reader charges by the tokens in the output it returns, so a long page costs proportionally more regardless of how hard it was to fetch.
On easy static pages, all three land near a fraction of a cent per page. On difficult ecommerce, news or social pages with anti-bot defenses, where the ILLUSTRATIVE success rate drops to 60%, the cost per attempted page rises to roughly $0.0042 (Firecrawl), $0.0024 (Jina), and $0.01 (Diffbot).
Firecrawl's and Diffbot's cost per successfully extracted page is 40–67% higher than their per-attempted-page cost, because a failed attempt still consumes a credit and must be retried; Jina's does not carry this penalty at all, because Jina does not charge for failed requests in the first place, so its per-successful-page cost equals its per-attempted-page cost divided by the success rate that already went into computing the attempted figure — in effect, Jina's billed cost tracks successful extractions directly.
On easy static pages, all three land near a fraction of a cent per page. On difficult ecommerce, news or social pages with anti-bot defenses, where the ILLUSTRATIVE success rate drops to 60%, the cost per attempted page rises to roughly $0.0042 (Firecrawl), $0.0024 (Jina), and $0.01 (Diffbot).
Here's the part that trips people up. Firecrawl's and Diffbot's cost per successfully extracted page is 40–67% higher than their per-attempted-page cost, because a failed attempt still burns a credit and has to be retried. Jina works differently: it doesn't charge for failed requests in the first place, so its billed cost tracks successful extractions directly. The per-successful-page figure is just the per-attempted figure divided by the success rate that already went into computing the attempted number.
My practical rule of thumb: don't compare these tools on sticker price alone. Compare them on your page mix. A scraper that looks cheap on static blog posts can quietly become your most expensive line item once anti-bot pages and retries enter the picture.
What each vendor bills
Firecrawl. Credit-based: Free (1,000 credits/month), Hobby ($16/mo, 5,000 credits), Standard ($83/mo, 100,000 credits), Growth ($333/mo, 500,000 credits), Scale ($599/mo, 1,000,000 credits). One credit is one basic scrape, crawl page, or map page. JavaScript rendering is automatic and included at no extra credit cost, which is a nice touch.
Jina AI Reader. Token-metered, not page-metered. Reader (r.jina.ai) converts a URL to markdown and bills for the tokens in the output it returns, at roughly $0.05 per million tokens. Every new API key includes 10 million free tokens, so you can kick the tires before opening your wallet. Failed requests are not charged, which means Jina's billing tracks successful extractions directly rather than every attempt.
Diffbot. Credit-based: Free (10,000 credits/month), Startup ($299/mo, 250,000 credits at $0.001 each), Plus ($899/mo, 1,000,000 credits at $0.0009 each, includes Crawl), Enterprise (custom). Extract 1 page = 1 credit; extract with a datacenter proxy = 2 credits. Knowledge Graph activities consume 25 to 100 credits per entity query, so keep an eye on those if you plan to lean on them.
Cost per 1 million attempted pages
This is the "what will the invoice look like" view, counting every page you try to fetch:
| Page mix | Firecrawl | Jina AI Reader | Diffbot |
|---|---|---|---|
| A: static | $830 | $85.50 | $1,000 |
| B: JS-heavy | $830 | $306.00 | $2,000 |
| C: difficult, with retries | $4,150 | $2,430.00 | $10,000 |
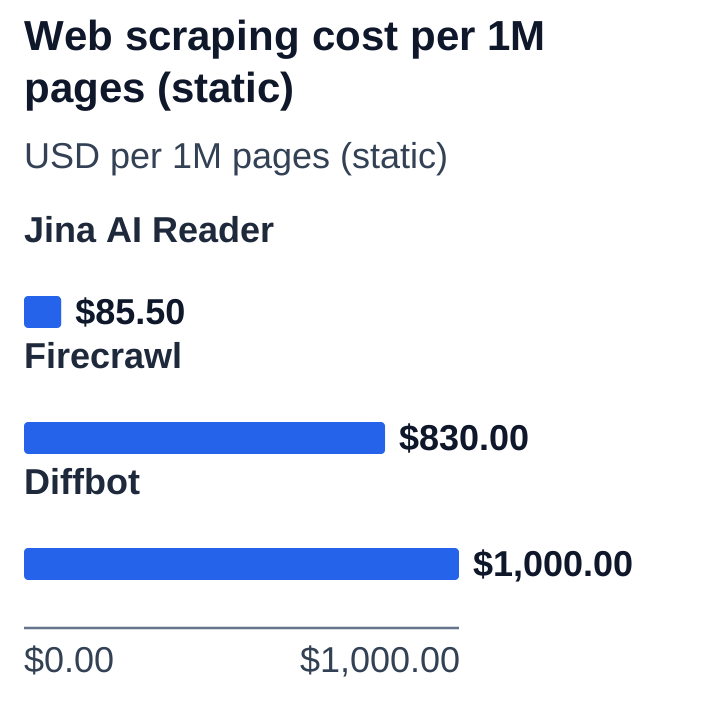
Cost per 1 million successfully extracted pages
A failed attempt on a difficult page isn't a usable result, so this is the view that matters for your actual pipeline output:
| Page mix | Success rate | Firecrawl, per successful page | Jina, per successful page | Diffbot, per successful page |
|---|---|---|---|---|
| A: static | 95% | $0.00087 | $0.00009 | $0.00105 |
| B: JS-heavy | 85% | $0.00098 | $0.00036 | $0.00235 |
| C: difficult, with retries | 60% | $0.00692 | $0.00405 | $0.01667 |
What to keep in mind: the gap between the two tables is where retries live. On static pages it's tiny. On the difficult mix it's big enough that it can change which vendor makes sense for you. In real-world production, I'd budget off the second table, not the first.
Interactive Matchup Simulator
Want numbers for your own setup? Plug in your target URL mix, page length, and expected anti-bot failure rate in our live calculator:
- Compare Firecrawl, Jina AI Reader, Diffbot, and self-hosted headless scrapers on the Interactive Web Extraction Matchup Simulator to plan your monthly ingestion pipeline.
Engineering Architecture Advice
- For Agentic Workflows & Clean Markdown RAG: Reach for Firecrawl. At $599 for 1,000,000 pages, it gives you the cleanest markdown formatting and the most robust sitemap crawling.
- For Lightweight Microservices & Variable Text Lengths: Reach for Jina AI Reader. Its token-based billing and zero-charge failure policy make it the most cost-effective option for short web lookups and agent tool calling.
- For Structured Product & Commercial Entity Catalogs: Reach for Diffbot. If your downstream database needs pre-classified product prices, SKUs, and author schemas without custom LLM extraction prompts, Diffbot's structured extraction justifies the enterprise price tag.
If you're still undecided, start with the free tiers and run a few thousand of your real URLs through each tool. Ten minutes of testing on your own pages will tell you more than any pricing page, and it won't cost you a cent.