Unsloth vs Axolotl vs Hugging Face TRL: Real Self-Hosted Fine-Tuning Cost per 100 Million Training Tokens in 2026
The bottom line: the core, single-GPU paths of all three frameworks are free and open-source, so at that scale there's no license fee to compare. Axolotl and Hugging Face TRL stay free at any GPU count, including multi-GPU. Unsloth's free tier is single-GPU only, and scaling it across multiple GPUs requires the paid Unsloth Pro subscription, whose price I couldn't confirm.
Within that free, single-GPU scope, the real cost difference is how many GPU-hours each framework needs to finish the same training job, and the gap is large. In a direct, same-hardware benchmark, Unsloth finished a fine-tuning run on a single A100 40GB in 3.2 hours, while Axolotl took 5.8 hours for the same job. That's a 1.8x speed gap, and it turns directly into GPU rental cost. Scaled to an ILLUSTRATIVE 100-million-training-token job on an A100 80GB at $1.43/hour, that works out to roughly $14.30 on Unsloth, $25.92 on Axolotl, and $28.60 to $71.50 on vanilla Hugging Face TRL (using Unsloth's own reported 2x-to-5x speed advantage over unoptimized TRL).
The bigger lever isn't speed, though, it's VRAM. Unsloth's memory reduction can turn a job that would otherwise need multiple GPUs into one that fits on a single consumer card. That's a categorical cost change, not a percentage one.
My practical rule of thumb: if your job fits on one GPU, start with Unsloth and see how far it gets you. If you know up front that you're going multi-GPU, go straight to Axolotl and skip the detour.
What each framework actually is, and what it costs
When engineering teams fine-tune open-source models, software licensing is rarely what drives the bill. All three frameworks ship open-source codebases with zero license fees for standard use:
- Unsloth: A specialized optimization engine that rewrites PyTorch kernels in OpenAI Triton. By manually deriving backpropagation steps and implementing custom matrix multiplications, Unsloth delivers 2x to 5x faster training speeds and 50% to 90% lower VRAM usage. Its core tier is free and open-source for single-GPU training. Multi-GPU distributed fine-tuning requires the proprietary Unsloth Pro tier.
- Axolotl: The open-source community standard for modular, configuration-driven fine-tuning. Built on PyTorch, Hugging Face Transformers, and DeepSpeed/FSDP2, Axolotl excels at distributed multi-GPU training at scale. It's 100% free and open-source at any GPU count, and you configure it entirely through declarative YAML files.
- Hugging Face TRL (Transformer Reinforcement Learning): The official Hugging Face library that provides the foundation for Supervised Fine-Tuning (SFT), DPO, and PPO. It integrates flawlessly with the Hugging Face ecosystem. The practical catch is that vanilla TRL, without custom kernel optimizations, runs slower and demands significantly more VRAM.
Since the code is free, the real cost of fine-tuning comes down to raw compute: GPU-hours required × hourly GPU rental price.
Cost is a function of GPU-hours needed, not a license fee
Formula: cost = GPU-hours required × hourly GPU rental rate.
To make this concrete, I'm using an ILLUSTRATIVE baseline of 10 GPU-hours on an A100 80GB (at a sourced $1.43/hour on-demand rate) for Unsloth to process 100 million training tokens via QLoRA. I then apply the framework-to-framework speed ratios found in the sources I reviewed:
| Framework | GPU-hours (ILLUSTRATIVE baseline × sourced speed ratio) | Cost at $1.43/hour (A100 80GB) |
|---|---|---|
| Unsloth | 10.0 | $14.30 |
| Axolotl | 18.1 (at the 1.8x ratio measured in a same-hardware A100 40GB benchmark) | $25.92 |
| Hugging Face TRL, low estimate | 20.0 (at Unsloth's reported 2x speed advantage) | $28.60 |
| Hugging Face TRL, high estimate | 50.0 (at Unsloth's reported 5x speed advantage) | $71.50 |
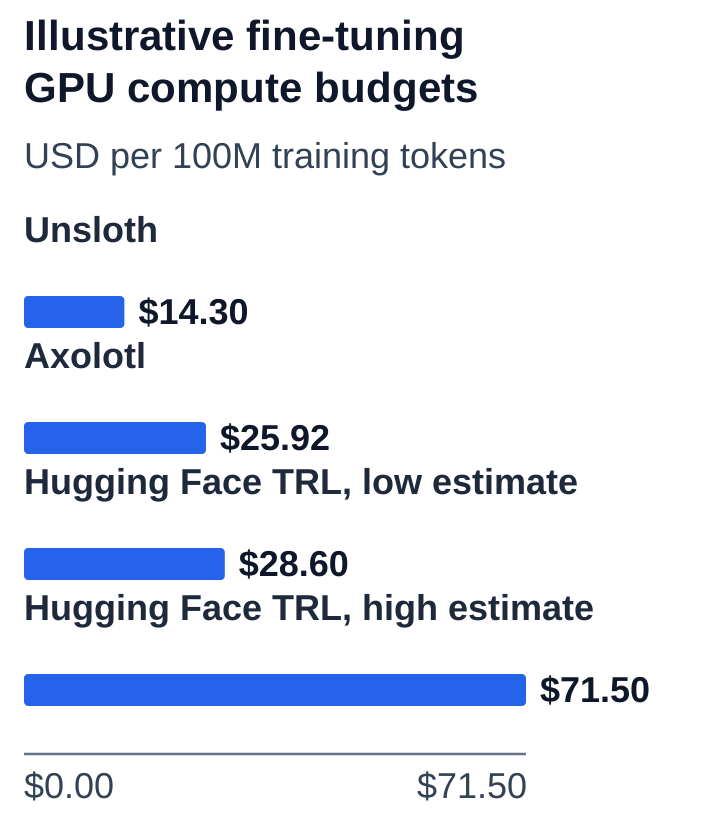
What to keep in mind: the 10-GPU-hour baseline is an ILLUSTRATIVE assumption, not a sourced figure for this exact token volume. What is sourced is the relative speed ratio between the frameworks. That ratio is what actually drives the cost comparison, whatever absolute baseline you pick.
The bigger lever: fitting on a cheaper GPU at all
Raw training speed gives you meaningful percentage savings, but Unsloth's VRAM reduction can save even more through hardware tier jumping.
In standard PyTorch and vanilla Hugging Face TRL, fine-tuning a 70B parameter model with QLoRA carries massive VRAM overhead for optimizer states, gradients, and activation memory. Teams routinely find that a 70B run won't fit on a single 24GB or 48GB GPU. That forces them to lease an enterprise 8x A100 or 8x H100 cluster costing $20.00 to $30.00+ per hour.
Unsloth's custom Triton kernels cut activation memory so drastically that a 70B parameter QLoRA fine-tune can fit on a single consumer GPU (like an RTX 3090 or RTX 4090 with 24GB VRAM) or a single A100 80GB. Renting an RTX 4090 on community cloud providers costs roughly $0.40 to $0.60 per hour, while a single A100 costs $1.43 to $1.80 per hour. Skipping the 8-GPU cluster turns an operation that would cost hundreds of dollars into a job that costs less than $20.
In real-world terms, this is the one to test first. Before you reserve a cluster, spend an afternoon checking whether your model actually fits on one card. It's a cheap experiment with a potentially huge payoff.
Where Axolotl's multi-GPU strength changes the calculus
Unsloth's main limitation is scale: its free tier is strictly single-GPU. When a job outgrows single-GPU memory, like full-parameter fine-tuning of 14B+ models or ultra-large dataset runs that need distributed parallelization, Axolotl takes the lead.
Axolotl natively integrates FSDP2 (Fully Sharded Data Parallel) and DeepSpeed ZeRO-3 without artificial license gating or paywalled tiers. For enterprise teams running distributed training on clusters of 8, 16, or 64 GPUs, Axolotl provides robust, battle-tested orchestration completely free of charge. Its slight single-GPU throughput deficit is quickly outweighed by not needing commercial software subscriptions to scale horizontally across multi-node infrastructure.
Sensitivity
- Model Parameter Size vs. Single-GPU VRAM: For 8B parameter models, memory constraints are manageable across all frameworks. For 70B models, Unsloth's memory optimization is the difference between leasing a single $1.43/hr GPU and an expensive $24.00/hr multi-GPU node.
- LoRA/QLoRA vs. Full Fine-Tuning: Parameter-efficient fine-tuning (LoRA/QLoRA) is where Unsloth's kernel rewrites shine brightest. Full parameter training demands distributed multi-GPU architectures, which is where Axolotl's FSDP2 infrastructure excels.
- Single-GPU vs. Distributed Cluster Requirements: Workloads that finish comfortably on a single GPU get the most out of Unsloth's speed and cost advantages. Massive distributed runs favor Axolotl's unrestricted open-source scaling.
- Cloud Provider Hourly Rates: On-demand data center GPUs (A100/H100) scale total compute expenses linearly. Spot instances or decentralized GPU clouds (RunPod, Lambda, Vast.ai) amplify framework efficiency savings even further.
Budgeting traps
- Treating these frameworks as commercial products with license fees: The software libraries are open-source, so the bill is pure GPU compute. The exception is optional commercial subscriptions like Unsloth Pro if you scale Unsloth across multiple GPUs.
- Sizing GPU instances based on vanilla TRL memory requirements: It's easy to overprovision multi-GPU clusters for QLoRA workloads before testing whether Unsloth can fit the model on a single card.
- Assuming Unsloth's free tier scales to multiple GPUs: Distributing Unsloth across multi-GPU setups requires a paid Pro license, and it's an unpleasant thing to discover mid-project.
- Treating benchmark baselines as absolute figures: Hardware throughput depends heavily on context sequence length, batch sizing, and dataset characteristics. Always validate training speeds on a small sample before committing to a multi-day training run.
What to ask before you buy
Can your target model and batch size fit onto a single GPU using QLoRA memory optimizations, so you can avoid multi-GPU cluster rental fees? Does your training pipeline need multi-GPU distributed scaling (where Axolotl is completely free) or single-card acceleration (where Unsloth is fastest)? And have you tested spot instance availability on specialized GPU clouds to cut hardware rental rates by an additional 50% to 70%?