OpenAI Prompt Caching vs Anthropic Prompt Caching vs Gemini Context Caching: Real Cost per 1 Billion Reused Tokens in 2026
The bottom line: all three caching mechanisms look alike from a distance (reuse a prefix, pay less), but they bill writes, reads and storage differently. At a 10-reads-per-write reuse ratio, 1 billion reused tokens costs $900 on GPT-5.6 Sol or $350 on Claude Sonnet 5.5 with a five-minute cache, against $4,400 and $2,200 respectively without caching. Sonnet 5.5's cache reads fell to $0.10/M on October 7, 2026, making its read multiplier 0.05x and the modeled saving 84.1%. Short-prompt Haiku 5.5 costs $22.50 for the same five-minute-cache token workload; prompts above 100K raise that to $112.50.
The catch is that Gemini's 3.8 Flash Standard explicit cache has no write premium but adds an ongoing storage fee. And if your reuse ratio is low, Anthropic's longer-TTL cache can end up costing you more than no cache at all.
My practical rule of thumb: if your prompts share a big static prefix and get hit repeatedly within minutes, turn caching on and stop worrying. If your traffic is sparse or bursty, read the break-even and storage sections below before you flip any switches.
Anthropic's prices were checked on October 9, 2026. The OpenAI and Gemini rows retain this article's October 1 snapshot. These comparisons hold billed token volume constant, so keep in mind that different tokenizers, capabilities and retry rates can change the cost of the same finished task.
Understanding how LLM prompt caching works under the hood
When a large language model processes a prompt, most of its compute time goes to converting incoming text into key-value (KV) attention matrices. For multi-turn chatbots, coding assistants with open files, or customer support bots loaded with company knowledge bases, identical prompt prefixes get sent to the model thousands of times a day.
Prompt caching skips that redundant work by keeping pre-computed KV attention states in high-speed GPU memory. When later API requests share the exact same prefix, the model bypasses re-computation. That cuts processing latency and lets providers discount input tokens by up to 90%–95%.
The three leading providers implement and monetize this in quite different ways:
- OpenAI (GPT-5.6 Sol): Uses an explicit caching structure. Creating a cache (a cache write) carries a 1.25x surcharge over the base input rate ($5.00/M vs $4.00/M), while cache reads receive a 90% discount ($0.40/M). An older, automatic prefix-matching mechanism still runs on earlier models without write fees, but provides variable discount depths.
- Anthropic (Claude Sonnet & Haiku 5.5): Uses developer-controlled ephemeral cache breakpoints (
cache_control: {"type": "ephemeral"}). A standard 5-minute time-to-live (TTL) cache write costs 1.25x ($2.50/M on Sonnet), while cache reads cost just 0.05x ($0.10/M, a remarkable 95% discount). A 1-hour extended TTL write costs 2.0x ($4.00/M). - Google Gemini (3.8 Flash Standard): Offers both implicit prefix caching and explicit
CachedContentobjects. Explicit cache creation carries no write surcharge (1.0x, $0.75/M), and cache reads receive a 90% discount ($0.075/M). Gemini does add an ongoing storage charge, though: $0.50 per million tokens per hour for as long as the cache object remains active.
Normalizing the workload: Reused tokens and the reuse ratio
In this analysis, 1 billion reused tokens means 1 billion tokens' worth of cache reads. To model the total cost honestly, we also have to count the initial cache writes needed to populate those caches.
The key economic variable is the reuse ratio: the average number of cache hits that occur before the cache expires or is evicted.
- At a 10:1 ratio, every cache write is read 10 times before expiration (100 million write tokens per 1 billion read tokens).
- At a 100:1 ratio, every cache write is read 100 times, spreading the write premium across a much higher volume of heavily discounted reads.
Formula: write tokens = reused tokens ÷ reuse ratio; total cost = (write tokens ÷ 1,000,000 × write rate) + (reused tokens ÷ 1,000,000 × read rate).
Cost per 1 billion reused tokens, at two reuse ratios
| Vendor / mechanism | Base input rate | Write rate | Read rate | Cost at 10:1 ratio | Cost at 100:1 ratio |
|---|---|---|---|---|---|
| Gemini 3.8 Flash Standard, explicit (token cost only, excludes storage) | $0.75/M | $0.75/M (1.0x) | $0.075/M (0.1x) | $150 | $83 |
| Claude Sonnet 5.5, 5-minute TTL | $2.00/M | $2.50/M (1.25x) | $0.10/M (0.05x) | $350 | $125 |
| Claude Sonnet 5.5, 1-hour TTL | $2.00/M | $4.00/M (2.0x) | $0.10/M (0.05x) | $500 | $140 |
| Claude Haiku 5.5, up to 100K prompt, 5-minute TTL | $0.10/M | $0.125/M (1.25x) | $0.01/M (0.1x) | $22.50 | $11.25 |
| Claude Haiku 5.5, over 100K prompt, 5-minute TTL | $0.50/M | $0.625/M (1.25x) | $0.05/M (0.1x) | $112.50 | $56.25 |
| GPT-5.6 Sol, explicit cache | $4.00/M | $5.00/M (1.25x) | $0.40/M (0.1x) | $900 | $450 |
At a 10:1 reuse ratio, Claude Sonnet 5.5 (5-minute TTL) delivers 1 billion reused tokens for just $350, compared to $900 on GPT-5.6 Sol and $150 on Gemini 3.8 Flash (excluding Gemini's storage fee). When the reuse ratio climbs to 100:1, the write surcharge becomes negligible, and Sonnet drops to $125 per billion tokens while Haiku 5.5 drops to an ultra-cheap $11.25.
TTL selection matters on Anthropic. Moving from a 5-minute TTL to a 1-hour TTL on Sonnet 5.5 raises the 10:1 cost from $350 to $500, because a 1-hour cache write costs 2.0x the base input rate instead of 1.25x.
Savings versus no caching at all
Formula: uncached cost = (write tokens + reused tokens) ÷ 1,000,000 × base input rate; savings % = (uncached − cached) ÷ uncached.
| Vendor / mechanism | Uncached cost, 10:1 ratio | Cached cost | Savings |
|---|---|---|---|
| Claude Sonnet 5.5, 5-minute TTL | $2,200 | $350 | 84.1% |
| Claude Haiku 5.5, up to 100K prompt, 5-minute TTL | $110 | $22.50 | 79.5% |
| Claude Haiku 5.5, over 100K prompt, 5-minute TTL | $550 | $112.50 | 79.5% |
| GPT-5.6 Sol, explicit cache | $4,400 | $900 | 79.5% |
| Gemini 3.8 Flash Standard, explicit (excl. storage) | $825 | $150 | 81.8% |
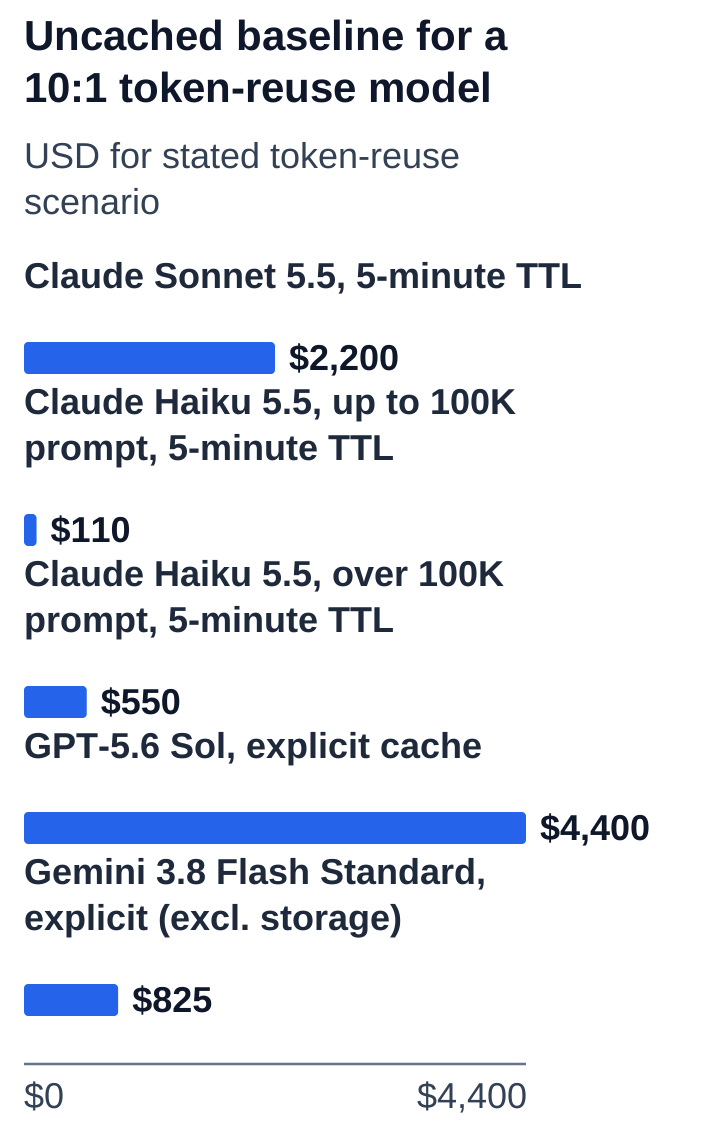
The modeled savings across all five configurations land in a tight band between 79.5% and 84.1%. On Claude Sonnet 5.5, caching saves $1,850 on every billion tokens processed at a 10:1 reuse ratio. On GPT-5.6 Sol, the savings amount to $3,500 per billion tokens.
Those percentages are pure efficiency gains. You get identical model outputs, identical context windows and better latency, while cutting your input token spend by roughly four-fifths. In real-world production, that's about as close to a free lunch as API pricing gets.
The break-even math: When caching actually costs you money
OpenAI and Anthropic both charge a write premium to establish a cache, so caching isn't automatically profitable for every query. If a cached prompt is evicted before it's read enough times, you end up paying more than if you had never enabled caching at all.
The break-even point comes from this formula: Break-even reads = (Write Multiplier − 1.0) ÷ (1.0 − Read Multiplier)
- For a 1.25x write multiplier and 0.10x read multiplier (e.g. GPT-5.6 or Haiku 5-min TTL):
Break-even = (1.25 − 1.0) ÷ (1.0 − 0.10) = 0.25 ÷ 0.90 = 0.28 reads. In whole numbers, that means exactly 1 subsequent read is needed to break even. If a prompt is cached once and read at least once before expiring, you save money.
- For Anthropic's 1-hour TTL (2.0x write multiplier and 0.05x read multiplier on Sonnet 5.5):
Break-even = (2.0 − 1.0) ÷ (1.0 − 0.05) = 1.0 ÷ 0.95 = 1.05 reads. In whole numbers, at least 2 subsequent reads are needed before expiration. If you cache a prompt for an hour but only read it once, you pay 2.0x + 0.05x = 2.05x the base rate, which is slightly more than two uncached requests (2.0x).
My rule of thumb: the 5-minute caches pay for themselves almost immediately, so they're a safe default. The 1-hour TTL is worth it only when you're confident each prefix will be hit at least twice within the hour.
The Gemini storage fee trap: When idle caches burn cash
Google Gemini's explicit caching has no token write surcharge, but its $0.50 per million tokens per hour storage fee adds an ongoing, time-based cost that neither OpenAI nor Anthropic has.
Consider a 100,000-token enterprise document repository cached explicitly for 24 hours. The storage fee alone is: 100,000 ÷ 1,000,000 × $0.50 × 24 hours = $1.20 per day ($36.00/month).
If that cache receives hundreds of queries per hour, the storage fee amortizes to a tiny fraction of a cent per request, and Gemini becomes exceptionally cheap. But if the cache sits idle over a weekend with zero queries, it keeps billing $1.20/day without delivering a single token discount. It's the cloud-era cousin of the forgotten subscription. For sparse or erratic workloads, Anthropic's and OpenAI's per-request TTL models give you far safer budgeting guarantees.
Architectural best practices for prompt caching
- Structure prompts hierarchically (the "Onion Architecture"): Put all static, heavy content at the very beginning of the prompt: system instructions, tool definitions, schemas and background reference manuals. Put dynamic, frequently changing content (current timestamp, user question, immediate turn history) at the very end. Caching engines match prefixes from the top down, so any change early in the prompt invalidates everything after it.
- Mind the prefix threshold: Providers enforce minimum prefix lengths before caching kicks in (typically 1,024 tokens for OpenAI and Anthropic, and 1,024 to 4,096 tokens for Gemini). A short 200-token system prompt will never trigger a cache hit.
- Use 5-minute TTLs for active conversational sessions: For live chat agents, a 5-minute TTL automatically refreshes on every incoming message. That keeps the conversation cache alive throughout an active session without paying the higher 1-hour write surcharge.