OpenAI Batch API vs Anthropic Message Batches vs Google Gemini Batch: Real Batch LLM Cost per 1 Billion Tokens in 2026
The bottom line: all three major providers discount asynchronous batch processing by exactly 50% off their standard synchronous rate, on both input and output tokens. I found no exceptions for any current-generation model from OpenAI, Anthropic, or Google. At an 80:20 input-to-output ratio, 1 billion tokens on a comparable mid-tier model (OpenAI's GPT-6 Sol or Anthropic's Claude Sonnet 5, both priced at $2/$10 per million tokens) costs $3,600 synchronous or $1,800 on batch. On Google's cheapest production-ready tier, Gemini 2.5 Flash-Lite, the same workload costs $160 synchronous or $80 on batch. The discount percentage is identical across vendors, so the underlying model's own rate is what actually decides your bill.
My practical rule of thumb: if nobody is waiting on the response, batch it. It's about the easiest 50% you'll ever save, and it rarely needs more than a small change to how you submit requests.
Why batch processing cuts inference bills in half
Frontier AI data centers have big peaks and valleys. During daytime business hours in North America and Europe, interactive chat traffic surges, and overnight, vast GPU clusters sit underutilized. To smooth out electricity and infrastructure demand, OpenAI, Anthropic, and Google all offer asynchronous batch processing lanes.
The trade is simple. You give up instant millisecond responses and accept a flexible completion window (typically within 24 hours, though Anthropic often completes jobs in under 4 hours). In return, the provider cuts your per-token invoice in half.
For engineering teams, batch APIs are one of the cleanest optimizations available. Any workload where a human isn't staring at a loading spinner should move off live synchronous endpoints and into batch queues. That covers overnight data extraction, catalog enrichment, sentiment analysis, synthetic dataset creation, and offline evaluation suites.
Reference rates across current production models
Because the 50% discount applies across all three vendors, comparing batch economics really comes down to comparing the models' underlying base prices:
- OpenAI GPT-6 Sol Standard: $2.00/M input and $10.00/M output for synchronous calls; exactly $1.00/M input and $5.00/M output in Batch mode.
- Anthropic Claude Sonnet 5: $2.00/M input and $10.00/M output synchronous; exactly $1.00/M input and $5.00/M output in Message Batches.
- Google Gemini 2.5 Flash-Lite: $0.10/M input and $0.40/M output synchronous; exactly $0.05/M input and $0.20/M output in Batch mode.
OpenAI's and Anthropic's mid-tier models are priced identically, which makes them a straight head-to-head comparison. Gemini 2.5 Flash-Lite sits in a different lightweight efficiency class, at roughly 20x cheaper per token.
Cost per volume, at an 80:20 input:output ratio
Formula: cost = (input millions × input rate) + (output millions × output rate), ILLUSTRATIVE 80% input / 20% output split.
| Model | 100M tokens, sync | 100M tokens, batch | 1B tokens, sync | 1B tokens, batch | 10B tokens, sync | 10B tokens, batch |
|---|---|---|---|---|---|---|
| OpenAI GPT-6 Sol | $360 | $180 | $3,600 | $1,800 | $36,000 | $18,000 |
| Anthropic Claude Sonnet 5 | $360 | $180 | $3,600 | $1,800 | $36,000 | $18,000 |
| Google Gemini 2.5 Flash-Lite | $16 | $8 | $160 | $80 | $1,600 | $800 |
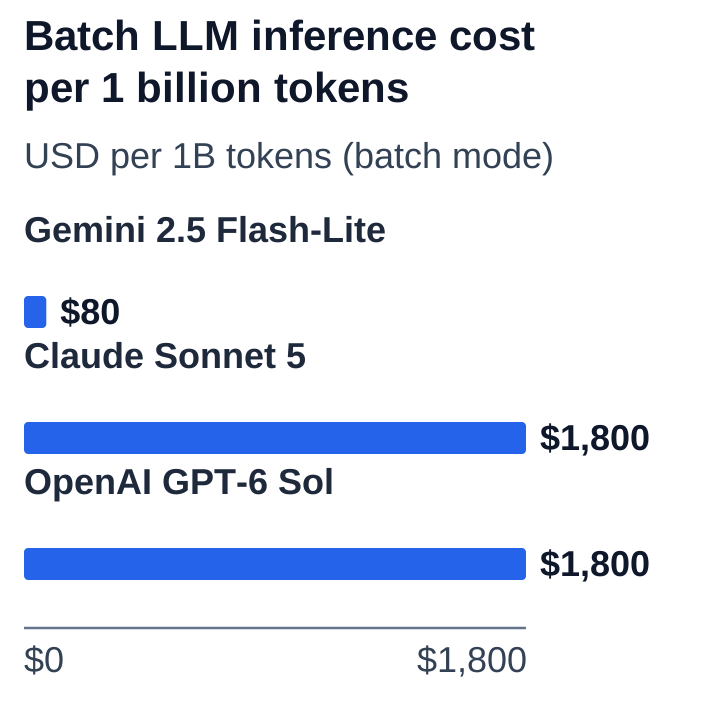
At every scale, the batch column cuts the synchronous invoice in half. At 1 billion tokens, batch processing saves $1,800 on GPT-6 Sol and Sonnet 5, and $80 on Gemini Flash-Lite. At 10 billion tokens, those savings scale to $18,000 and $800 respectively.
The bigger lever, though, is model choice. Batch processing gives you a 2x cost advantage, while model selection gives you a 22.5x advantage. If your workload is routine, like text classification, summarization of structured data, or entity extraction, routing to a lightweight model like Gemini 2.5 Flash-Lite in batch mode drops a $36,000 synchronous mid-tier bill to just $800. That's a 97.8% total reduction.
In real-world production, I'd always test the small model first on a sample of your data. If quality holds up, you've just saved far more than any discount code could. If it doesn't, you've lost an afternoon and gained a clear answer.
The truncation trap: Paying for tokens you discard
One of the easiest budgeting mistakes with batch APIs is forgetting that providers bill for all tokens generated by the model, whether or not your downstream application parses them.
In an interactive chat UI, a user might interrupt a rambling response, or your app might abort streaming. Batch requests run completely unattended. Say your prompt asks for a one-sentence summary but you omit a strict max_tokens cap. The model might happily write a 1,500-token explanation. If your script parses only the first sentence and discards the rest, you're still billed for all 1,500 output tokens.
Output tokens cost 4x to 5x more than input tokens on major frontier models ($5.00/M vs $1.00/M on batch), so accidental verbosity can multiply your batch invoice by several hundred percent. A few habits keep this in check:
- Set an explicit
max_tokenscap on every request line in your.jsonlpayload. - Use structured outputs (JSON schema enforcement) to prevent explanatory filler text.
- Tune system prompts with few-shot examples that demonstrate the exact desired brevity.
The ultimate multiplier: Stacking batch processing with prompt caching
All three providers offer the same 50% batch discount, but Anthropic has one standout trick: stacking Message Batches with Prompt Caching.
Say you're processing large volumes of documents against a shared prompt, such as a 40,000-token legal handbook, API specification, or codebase repository. Anthropic allows batch requests to hit cached prompt prefixes. A cached prompt read on Claude Sonnet receives a 90% to 95% discount off the base rate, and when processed through a batch lane, that discount stacks further.
A cached-and-batched request on Anthropic can cost as little as 5% of the standard non-cached synchronous rate for the same model. Neither OpenAI nor Google currently documents identical stacking depth across their serverless batch pipelines. For document-heavy backfills and large evaluation suites, this combined discount makes Anthropic remarkably cost-effective.
Operational mechanics and failure handling
Batch APIs work a little differently from synchronous ones. Here's the typical flow:
- Payload creation: You package your requests into a standard JSON Lines (
.jsonl) file, where each line contains a unique custom ID and standard request parameters. - File upload and job submission: You upload the file via the vendor's files endpoint, then start the batch job, specifying the endpoint (e.g.
/v1/chat/completionsor/v1/messages). - Status polling: Your backend polls the batch job status periodically. Both OpenAI and Anthropic provide webhooks or status endpoints indicating progress (
in_progress,completed,cancelling). - Partial failure resilience: A single giant API request fails completely on an error, but batch jobs process requests independently. If 5 out of 10,000 lines contain invalid parameters or hit context limits, the remaining 9,995 requests succeed and are billed normally. The results file clearly flags individual line errors with HTTP error codes.
When to batch and when to keep it real-time
- Choose Synchronous APIs if: A user is actively waiting on an interface, the response drives an automated real-time transaction, or your system relies on immediate bidirectional conversational flow.
- Choose Batch APIs if: Processing can happen in the background within a few hours, you're backfilling historical databases, generating synthetic test data, running bulk offline regressions, or indexing large archives for semantic search.
If you're unsure which bucket a workload falls into, ask whether anyone would notice if the results arrived a few hours later. If the answer is no, batch it and enjoy the smaller invoice.