ElevenLabs Voice Agent: Real Production Cost and Overage Economics (2026)
The bottom line: ElevenLabs Voice Agents are billed on a dedicated per-minute conversation meter against your subscription's monthly allowance. That meter is completely separate from the character and credit pool used for standard text-to-speech, dubbing, or audio generation. Every plan from Starter through Business bundles an included bucket of minutes and an active concurrency ceiling. If you stay within both, your effective voice infrastructure costs hover around $0.08 to $0.10 per minute.
The catch is that once your traffic spikes beyond your concurrency limit, ElevenLabs doubles your overage rate to $0.16 per minute. Also, the advertised rate covers only speech-to-text, synthesis, and turn coordination. The reasoning LLM and carrier telephony are billed separately on pass-through meters, adding roughly $0.035 to $0.07 per minute in real production deployments.
My practical rule of thumb: size your plan around your peak concurrency, not your monthly minutes. The minute math is easy. The concurrency math is where the surprises hide.
Pricing at a glance
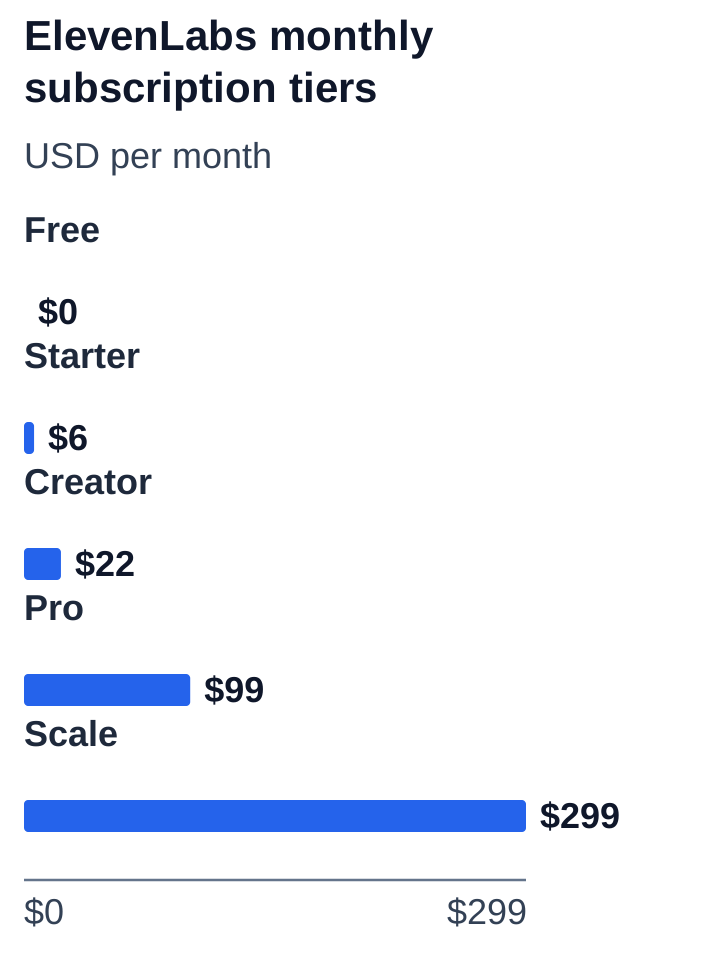
| Plan | Monthly price | Included call minutes | Concurrent calls included |
|---|---|---|---|
| Free | $0 | 15 | 4 |
| Starter | $6 | 75 | 6 |
| Creator | $22 ($11 first month) | 275 | 10 |
| Pro | $99 | 1,238 | 20 |
| Scale | $299 | 3,738 | 30 |
| Business | $990 | 12,375 | 40 |
| Enterprise | Custom | Custom | Custom |
| Usage beyond plan limits | Rate |
|---|---|
| Additional minutes (within concurrency limit) | $0.08/min |
| Burst minutes (over the concurrency limit) | $0.16/min (double the standard overage rate) |
| Text messages sent by the agent | $0.003 each |
| LLM (the model powering the conversation) | Billed separately by ElevenLabs, at the connected model's own per-token rate — not included in the per-minute Agents price |
Source: elevenlabs.io/pricing/agents and elevenlabs.io/pricing.
What the per-minute rate does — and doesn't — cover
ElevenLabs built its conversational agent platform as a unified turn-key pipeline. That $0.08–$0.10/min rate pays for low-latency Speech-to-Text (STT), natural conversational audio synthesis via ElevenLabs' flagship voices, interruption handling, and WebSocket audio streaming.
Here's what the base price deliberately leaves out:
- The Brain (Language Model): Every spoken turn has to be processed by an LLM (such as GPT-4o, Claude 3.5 Sonnet, or Gemini 1.5 Flash). ElevenLabs bills these tokens separately, based on the exact provider rates without markup. In typical inbound customer service dialogues, a realistic system prompt with moderate context length adds $0.02 to $0.05 per conversation minute on GPT-4o-class models.
- Carrier Telephony: Connecting your agent to real-world phone lines requires SIP trunking or PSTN carriers (such as Twilio, Vonage, or Telnyx). That adds another $0.010 to $0.015 per minute directly on your carrier bill.
- Studio Audio Credits: ElevenLabs' standard voice cloning, long-form TTS, dubbing, and audio isolation tools continue to draw from your account's character credit pool. They don't share minutes with conversational agents.
Hidden costs to model before you launch
- The concurrency trap doubles your rate in seconds. Say you're on the Pro plan (20 concurrent calls) and a marketing blast causes 35 customers to call at the same time. Those 15 extra callers aren't rejected. They're billed at $0.16/min instead of $0.08/min. A business sized for median daily traffic rather than morning peak volume will routinely overpay.
- LLM token pass-through is the biggest surprise on the invoice. The ElevenLabs dashboard puts minutes front and center, so it's easy to forget that a 5-minute diagnostic call with a verbose 2,000-token system prompt consumes serious LLM context. At $0.035/min, the LLM alone can represent 30% to 45% of your all-in operational spend.
- Preemptive tier upgrades need volume math. Upgrading from Pro ($99/mo for 1,238 minutes) to Scale ($299/mo for 3,738 minutes) delivers minutes at roughly $0.08 each. If your team only uses 2,000 minutes a month, you could stay on Pro and pay the standard $0.08/min overage for the extra 762 minutes. That costs $159.96 total, saving you nearly $140 compared to jumping to Scale early.
- Free and Starter tiers are sandboxes, not production infrastructure. With concurrency caps of 4 and 6 simultaneous calls, even a family-owned medical clinic or local appointment desk will trigger burst penalties during regular operating hours.
Worked production scenarios
To show realistic all-in production economics, we model a customer support and inbound scheduling agent running GPT-4o (at a representative $0.035/min LLM consumption) across three operational profiles.
Scenario A — 1,000 minutes/month, steady distribution (no concurrency bursts)
- Selected plan: Pro ($99/month, 1,238 minutes included — comfortably covers volume)
- LLM pass-through: 1,000 min × $0.035 = $35
- Telephony allowance: handled via SIP carrier (~$15)
- Total ElevenLabs invoice: $99 + $35 = $134/month ($0.134 per minute all-in)
Scenario B — 5,000 minutes/month, steady operational volume
- Selected plan: Scale ($299/month, 3,738 minutes included; 1,262 overage minutes)
- Standard overage: 1,262 min × $0.08 = $100.96
- LLM pass-through: 5,000 min × $0.035 = $175
- Total ElevenLabs invoice: $299 + $100.96 + $175 = $574.96/month ($0.115 per minute all-in)
Scenario C — 15,000 minutes/month, peak hours exceed Business concurrency (40 calls)
- Burst-rate minutes: 1,500 min × $0.16 = $240 - Standard overage minutes: 1,125 min × $0.08 = $90
- Selected plan: Business ($990/month, 12,375 minutes included; 2,625 overage minutes)
- Assume peak morning bursts push 10% of total volume (1,500 minutes) beyond the 40-call concurrency limit:
- LLM pass-through: 15,000 min × $0.035 = $525
- Total ElevenLabs invoice: $990 + $240 + $90 + $525 = $1,845/month ($0.123 per minute all-in)
Break-even: ElevenLabs vs. modular voice stacks (Vapi and Retell)
So how does ElevenLabs' bundled approach stack up against modular voice platforms like Retell or Vapi?
Take Scenario B (5,000 minutes/month at $574.96 total on ElevenLabs). On a modular stack like Retell, you assemble your own components. Retell charges $0.055/min for core orchestration, plus roughly $0.015/min for standard voice synthesis, $0.015/min for telephony, and the same GPT-4o model at $0.035/min. That adds up to $0.120 per minute, or $600 per month for 5,000 minutes.
At this mid-tier volume, ElevenLabs actually comes out $25/month cheaper than assembling a modular stack. ElevenLabs bundles its proprietary TTS engine at a favorable blended rate inside its higher subscription tiers.
The picture shifts toward modular platforms at high volumes (50,000+ minutes/month) or when fine-grained engineering control is critical:
1. Model routing flexibility: Modular platforms let you route simple conversational turns to lightning-fast, ultra-cheap models (like Gemini 1.5 Flash or Groq Llama 3.3 at $0.002/min) and reserve frontier models only for complex escalations. 2. True cost pass-through: Platforms like Vapi and Retell don't levy a 100% burst penalty when concurrency spikes. They scale dynamically on your cloud infrastructure.
In real-world production, a $25 gap at mid-volume is basically a rounding error. I'd pick based on voice quality, how much control your team wants, and how spiky your traffic is, rather than chasing the cheapest line item.
Practical buying recommendations
- For teams prioritizing voice realism and speed to market: If audio expressiveness, emotional cadence, and single-dashboard simplicity matter most, ElevenLabs delivers exceptional quality out of the box, with an effective total cost between $0.11 and $0.14 per minute.
- Monitor peak concurrent channels, not just monthly minutes: Review your call records for maximum simultaneous calls during lunch hours or sales promotions. Upgrading to Business solely for the 40-channel concurrency cushion can easily save hundreds in burst penalties.
- Optimize your LLM system prompt: Keep instructions compact and use prompt caching or concise function definitions to minimize per-minute token charges. Trimming a bloated prompt is the cheapest "upgrade" you'll ever make.
If you're comparing managed minutes with an assembled stack, see Vapi vs Retell vs Bland. For non-agent speech generation, compare ElevenLabs API cost per minute.
Methodology and pricing verification
- Regular plan rates, included minutes, and overage rules were confirmed against ElevenLabs' published documentation and live billing dashboards.
- LLM pass-through costs reflect typical customer service prompts on frontier models (e.g., GPT-4o input/output token pricing).
- Telephony costs assume standard US/EU inbound SIP trunking rates via Twilio or Telnyx.
Official sources
- elevenlabs.io/pricing
- elevenlabs.io/pricing/agents
- elevenlabs.io/pricing/api