Kimi K3 Isn't the Cheap Chinese Model You Expected — Here's What It Actually Costs
Executive summary
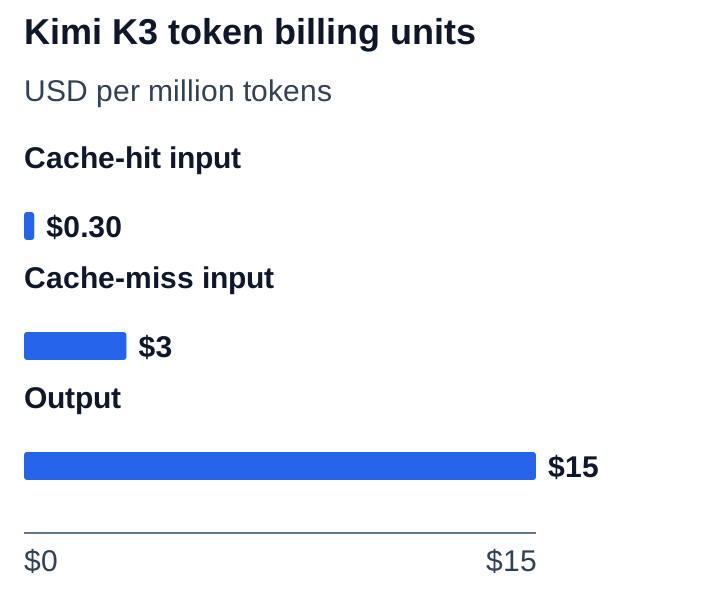
Kimi K3, Moonshot AI's flagship model, is not priced like DeepSeek or Qwen's budget tiers. Its official API rate — confirmed directly on Moonshot's own pricing documentation — is $3.00 per million input tokens and $15.00 per million output tokens, with a $0.30 per million cache-hit rate. That's the same pricing tier as Claude Sonnet, not the sub-dollar rates that "cheap Chinese model" coverage might lead you to expect. What actually makes K3 economically interesting is its 1,048,576-token context window combined with that cache-hit discount: workloads that repeatedly reuse a large context can push effective cost down toward $0.30/M, while workloads that don't — short chats, one-off prompts, or reasoning-heavy tasks with long outputs — pay close to full price on a model whose output rate is 50x its cache-hit input rate. This article works through the actual math rather than the sticker price.
The bottom line: Kimi K3 isn't a bargain-basement clone — it's priced like Claude Sonnet ($3/M in, $15/M out). If you have large, persistent contexts that hit the 90% cache discount ($0.30/M), it's very cost-effective. If your workload is mostly short, one-off prompts or heavy reasoning output, you'll pay full freight.
My practical rule of thumb: don't look at K3 to cut costs on lightweight chatbots. Look at it when you're repeatedly querying massive codebases or 500-page document sets where that 1M context window and cache discount actually move the needle.
What is Kimi K3?
Moonshot AI launched Kimi K3 as an API endpoint in July 2026, accompanied by open-weight releases on Hugging Face:
- 2.8 trillion total parameters with 104 billion active per token: Built on Moonshot's Stable LatentMoE architecture, routing each token to 16 out of 896 specialized experts. It is among the largest sparse Mixture-of-Experts architectures available outside closed research labs.
- 1,048,576-token context capacity: Fully supported on the official developer platform, enabling whole-repository codebase analysis and massive book-length context ingestion.
- Native multimodal architecture: Processes high-resolution imagery and complex documents through a unified vision-language pipeline rather than routing through an external vision adapter.
- Benchmark performance: Independent evaluations on the Artificial Analysis Intelligence Index score K3 alongside frontier systems like Claude Opus 4.8 and GPT-5.5, with exceptional performance in multi-step agentic workflows and tool-calling automation.
API pricing — the real numbers
Moonshot's model pricing documentation (platform.moonshot.ai/docs/pricing, mirrored at platform.kimi.ai) lists:
| Model | Cache-hit input | Cache-miss input | Output | Context window |
|---|---|---|---|---|
| kimi-k3 | $0.30 / M | $3.00 / M | $15.00 / M | 1,048,576 tokens |
| kimi-k2.7-code | $0.19 / M | $0.95 / M | $4.00 / M | 262,144 tokens |
| kimi-k2.7-code-highspeed | $0.38 / M | $1.90 / M | $8.00 / M | 262,144 tokens |
| kimi-k2.6 | $0.16 / M | $0.95 / M | $4.00 / M | 262,144 tokens |
Earlier generational checkpoints like K2.5 and the legacy moonshot-v1 family have been fully retired from the active API catalog.
Web Search Tool Integration: K3 supports an integrated $web_search tool billed at $0.005 per execution, with returned search snippets billed as standard input tokens on the subsequent inference turn. Standalone REST search endpoints are also available for external data gathering at $0.002 to $0.003 per query.
The market reality: At $3/$15, Kimi K3 is roughly 40% cheaper than Claude Opus 5 ($5/$25), but it is not intended to compete with sub-dollar flash models like DeepSeek Flash ($0.15–$0.30/M) or Qwen-Flash. It is designed as an enterprise-grade reasoning engine.
Consumer subscription plans (kimi.com)
Alongside its metered developer API, Moonshot provides consumer and professional web/mobile subscriptions:
- Free Tier (Adagio): Basic web chat access with daily rate limits.
- Paid Subscriptions: Ranging from Moderato ($19/mo) and Allegretto ($39/mo) up to Allegro ($99/mo) and Vivace ($199/mo), scaling agent concurrency, Kimi Code terminal access, and extended context limits.
Note that web app subscriptions operate on independent account wallets and do not provide API credits for developer endpoints.
Context caching: why the cache-hit rate is the number that matters
Moonshot's automatic prompt caching is the foundational mechanism that unlocks K3's cost efficiency. By reducing input token billing from $3.00/M down to $0.30/M for cached prefixes, it provides a 10x discount on reused data.
How to structure calls for maximum caching: Ingesting a 300,000-token software repository costs roughly $0.90 on the first API request. If subsequent user questions query that same cached repository prefix, each query incurs only $0.09 for the context plus the incremental cost of the new prompt and reply. In active developer workflows with a 90% cache-hit rate, the blended input cost drops to roughly $0.57 per million tokens.
The critical caveat: Caching only provides savings when there is persistent, reusable context. Applications executing short, isolated, single-turn prompts receive zero caching benefits and pay the full $3.00/M input tariff.
The long-document example costs $0.36, about 12.5 times the coding-task example at $0.0289. This is not a controlled comparison of context length alone: the coding task uses K2.7 Code, while the long-document task uses K3, with different token rates, input volumes, cache shares and output volumes. Caching reduces the input rate; total cost still depends on every billed input and output token.
Reasoning cost: the part that can quietly dominate your bill
Kimi K3 employs an always-on internal reasoning mechanism. The model evaluates questions via chain-of-thought trajectories controlled by a reasoning_effort parameter (low, medium, max).
The economic consequence is direct: reasoning tokens are billed as output tokens, at K3's $15.00/M output rate — 50x the cache-hit input rate and 5x the cache-miss input rate. Output tokens receive no input-cache discount. For any task where the model reasons at length before answering, the reasoning tokens themselves — not the visible answer — can be the majority of what you're actually paying for. This is precisely why the executive summary above singles out "reasoning-heavy tasks with long outputs" as a weak economic fit: there's no cache discount available to soften that side of the bill, and it's a fixed behavior of the model, not a setting you can turn off to save money.
When architecting high-volume workflows, calibrate reasoning_effort carefully to avoid overpaying for unnecessary deliberation on simple queries.
Kimi K3 on Amazon Bedrock
For global enterprise organizations seeking Western cloud infrastructure, Kimi K3 is available on Amazon Bedrock:
- Cross-Region Inference: Deployable via US Geo profiles (
us.moonshotai.kimi-k3) for strict US data residency, or Global profiles (global.moonshotai.kimi-k3) which leverage worldwide spare capacity for approximately 10% lower pricing. - Enterprise Data Boundaries: Invocations execute within AWS's strict isolation perimeters; prompts and generations remain fully inside your AWS Virtual Private Cloud (VPC) and are never shared with external model developers or used for training.
- Prompt Caching on Bedrock: K3 represents the first open-weight architecture on Amazon Bedrock to support native prompt caching.
Open-weight licensing and self-hosting reality
While Moonshot released K3's weights under the Kimi K3 License on Hugging Face, running the model locally is fundamentally an enterprise data-center undertaking:
- Permissive commercial use: The license grants free commercial use, modification, and deployment rights for internal enterprise applications and standard SaaS products.
- Model-as-a-Service thresholds: Companies reselling direct raw inference to third parties that generate over $20 million in trailing 12-month revenue must coordinate licensing agreements with Moonshot.
- Hardware footprint: K3's model weights span 1.56 TB across 96 safetensors shards. Running the model efficiently requires a cluster of 8 to 16 enterprise 80GB GPUs (such as NVIDIA H100 or H200 systems) with high-bandwidth interconnects. For the vast majority of engineering teams, calling the hosted API or Amazon Bedrock is vastly cheaper and simpler than maintaining self-hosted supernodes.
Practical takeaways for production teams
- Leverage K3 for large-context reasoning: K3 delivers its greatest ROI when analyzing extensive codebases, legal contracts, or multi-document knowledge graphs where its 1M context and 90% cache discount compound.
- Control reasoning depth on routine tasks: Set
reasoning_effortto low for classification, extraction, or structured data formatting to prevent output token inflation. - Use Bedrock for regulated workloads: If corporate compliance requires SOC 2, HIPAA, or strict US data localization, Bedrock provides compliant infrastructure with identical model performance.