Hugging Face Inference Endpoints vs AWS SageMaker vs Google Vertex AI: Real Managed Model Hosting Cost in 2026
The bottom line: a dedicated GPU endpoint bills by the hour whether or not a request arrives, so the listed instance price is only the starting point. At 10% utilization, a single L4-class endpoint's effective cost per utilized GPU hour is roughly 8 to 10 times its listed hourly rate on all three platforms. At 70% utilization, that premium shrinks to about 1.1 to 1.4 times.
The catch is that Hugging Face's own documentation is internally inconsistent on H100 pricing. One current doc page lists no AWS H100 tier at all, jumping from A100 to H200, while another current HF doc page lists an AWS H100 x1 rate of $4.50 an hour. I'll flag that conflict here rather than quietly picking one. None of the three platforms' listed instance prices is the full production cost either: autoscaling, storage, networking, load balancing and monitoring all sit on top.
My practical rule of thumb: the platform you pick matters less than how busy you keep the GPU. Get utilization right first, then compare logos.
What each platform bills for the instance itself
Dedicated model hosting works differently from serverless token APIs. Instead of paying per generated token, you lease raw GPU hardware around the clock. The core hourly rate depends on the platform and instance tier.
Hugging Face Inference Endpoints offers a turnkey, developer-first experience where you can deploy any model from the Hub in two clicks. On AWS infrastructure, entry-level T4 GPUs start at $0.50/hr, L4 at $0.80/hr, A10G at $1.00/hr, and single A100 80GB GPUs run at $2.50/hr (scaling to 8x A100 at $20.00/hr). On Google Cloud infrastructure, pricing shifts: an L4 costs $0.70/hr, while a single A100 costs $3.60/hr. So your choice of cloud provider inside Hugging Face directly changes your monthly hardware spend.
AWS SageMaker endpoints bill continuously while in service. Standard real-time endpoints running medium GPUs (T4 or L4 class) run between $0.45 and $1.70 per hour depending on memory and instance sizing. Enterprise multi-GPU clusters (ml.p4d.24xlarge with 8x A100 80GB) cost roughly $32 or more per hour (approximately $4.00 per A100 GPU-hour). SageMaker also integrates tightly with AWS IAM roles, VPC peering, and CloudWatch metrics, which is a real plus if you already live in AWS.
Google Cloud Vertex AI bills for the underlying Compute Engine machine plus attached GPU accelerators, alongside a dedicated Vertex management fee. A single A100 GPU in us-central1 costs roughly $2.93/hr for compute plus $0.44/hr in management fees, totaling approximately $3.37 per hour. Like SageMaker, endpoints keep accumulating hourly charges even during zero-traffic windows.
Three configurations and three utilization levels
The configurations are illustrative groupings mapped onto each platform's published or reported per-GPU rate. The 16-GPU row scales the per-GPU rate linearly as a production reference:
| Configuration | Hugging Face (AWS A100 basis) | SageMaker (A100-equivalent) | Vertex AI (A100 basis) |
|---|---|---|---|
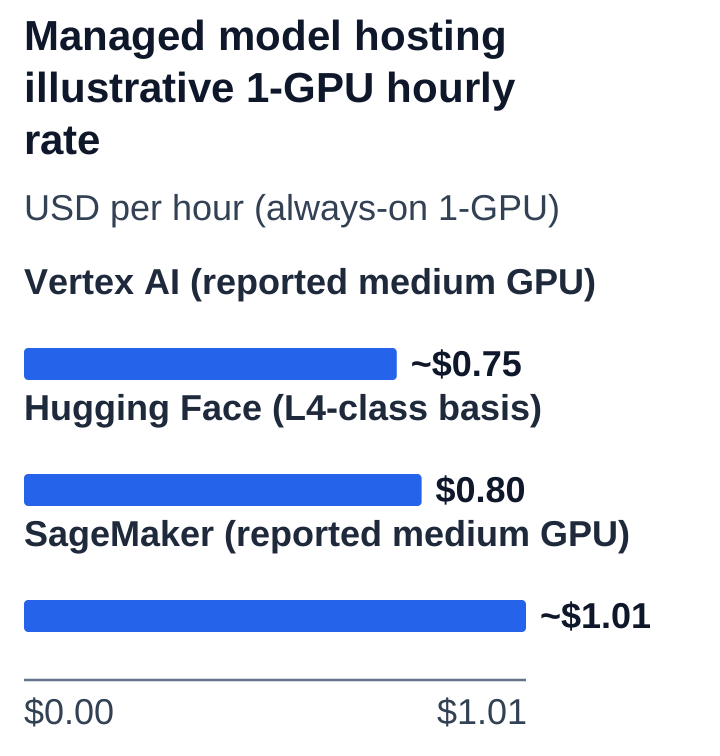
| 1 GPU (L4-class) | $0.80/hr ($584/mo at 730 hrs) | ~$1.01/hr (medium-GPU reported range, ~$734/mo) | ~$0.75/hr (reported medium-GPU range, ~$548/mo) |
| 4 GPU (A100-class) | $10.00/hr ($7,300/mo) | ~$16.00/hr (4× the ~$4.00 A100-equivalent rate, $11,680/mo) | ~$13.48/hr (4× $3.37, $9,840/mo) |
| 16 GPU (A100-class production, linear extrapolation) | ~$40.00/hr (linear extrapolation beyond HF's published x8 ceiling, ~$29,200/mo) | ~$64.00/hr ($46,720/mo) | ~$53.92/hr ($39,362/mo) |
Effective cost per utilized GPU hour
Here's the formula: effective cost per utilized GPU hour = (listed hourly rate ÷ GPU count) ÷ utilization. Dedicated instances bill identically whether they serve one request or ten thousand, so low traffic hits your unit economics hard:
| Configuration | Platform | 10% utilization | 30% utilization | 70% utilization |
|---|---|---|---|---|
| 1 GPU | Hugging Face | $8.00 | $2.67 | $1.14 |
| 1 GPU | SageMaker | $10.06 | $3.35 | $1.44 |
| 1 GPU | Vertex AI | $7.50 | $2.50 | $1.07 |
| 4 GPU | Hugging Face | $25.00 | $8.33 | $3.57 |
| 4 GPU | SageMaker | $40.00 | $13.33 | $5.71 |
| 4 GPU | Vertex AI | $33.70 | $11.23 | $4.81 |
| 16 GPU | Hugging Face | $25.00 | $8.33 | $3.57 |
| 16 GPU | SageMaker | $40.00 | $13.33 | $5.71 |
| 16 GPU | Vertex AI | $33.70 | $11.23 | $4.81 |
At 10% hardware utilization, which is common during development or for internal corporate tools, an A100 endpoint on SageMaker effectively costs $40.00 per productive hour. Dedicated hosting only reaches its intended cost efficiency once sustained utilization climbs toward 70%.
In real-world production, that means an endpoint that looks cheap on the pricing page can be one of the pricier line items in your bill if it mostly sits idle. If your traffic is a trickle, the table above is a good reason to pause before reaching for dedicated hardware.
Break-even against serverless API inference
Choosing between dedicated hosting and serverless token APIs comes down to how predictable and how large your traffic is:
- When serverless APIs win: If query volume is intermittent, bursty, or below a few million tokens a day, serverless endpoints (Together AI, Fireworks, Groq, Bedrock) are significantly cheaper. Paying per token means zero waste on idle nights and weekend troughs.
- When dedicated hosting wins: Once an application generates consistent, 24/7 high-throughput traffic (such as 3 to 5 billion tokens per month for a 70B model), dedicated multi-GPU clusters achieve lower per-token costs. You also get strict latency guarantees and complete data isolation.
What the listed price leaves out
A very common budgeting slip is treating the baseline hourly instance rate as the whole monthly invoice. In production, the supporting cast adds up:
- Persistent high-speed storage: Hosting large model weights requires provisioned SSD volumes (such as AWS EBS gp3 or io2), adding $50 to $200+ monthly per endpoint.
- Autoscaling and cold starts: Spinning up a new GPU node means pulling container images and loading tens of gigabytes of weights into VRAM, which often takes 5 to 10 minutes. Teams frequently overprovision minimum instance counts to avoid request timeouts.
- Documentation inconsistencies: Hugging Face's own documentation is internally inconsistent on H100 pricing. One current doc page lists no AWS H100 tier at all, jumping from A100 to H200, while another current HF doc page lists an AWS H100 x1 rate of $4.50 an hour. It pays to note that contradiction upfront rather than picking one number silently. Before you budget around H100s, double-check the live pricing in your own console.
- VPC networking and egress: Routing inference traffic across private enterprise subnets and Availability Zones incurs standard cloud data transfer charges.
Sensitivity
- Traffic consistency vs. idle waste: Steady 24/7 workloads get the most out of dedicated hardware. Variable workloads with quiet nights suffer heavy idle penalties unless you configure responsive scale-to-zero.
- Model footprint vs. VRAM requirements: Compact 8B models run comfortably on a single inexpensive L4 or A10G instance (~$550–$730/mo). Full 70B models need multi-GPU nodes ($7,300 to $11,680/mo) unless quantized.
- Scale-to-zero implementation: Hugging Face supports automatic scale-to-zero natively, pausing instances during inactivity. SageMaker and Vertex AI offer asynchronous or serverless configurations, though you'll want to test warm-up latencies against what your users will tolerate.
Budgeting traps
- Leaving ghost endpoints running: Forgetting to shut down test endpoints after an experiment keeps billing hundreds of dollars each week with zero active traffic. We've all had that one forgotten endpoint.
- Underestimating weight loading times during autoscaling: Leaning on aggressive autoscaling for latency-critical, user-facing apps often leads to dropped connections during sudden traffic spikes.
- Switching from serverless APIs prematurely: Moving to dedicated GPU instances before you've validated steady query volume is a classic source of wasted infrastructure spend.
What to ask before you buy
Before you commit, run through three questions:
- What is your expected average GPU utilization across 24 hours, including nights and weekends?
- Can your user experience accommodate cold-start latency if instances scale to zero during idle periods?
- Have you included storage volumes, load balancers, and egress data transfer in your monthly hosting forecast?
If you can answer all three confidently, dedicated hosting is likely a good fit. If you're guessing on the first one, start with serverless and graduate once the traffic proves itself.