Braintrust vs Humanloop vs LangSmith: Real LLM Evaluation Cost per 100,000 Eval Runs in 2026
The short answer: for evaluation work, human review time can dominate total cost once a workload samples a meaningful share of runs for human checking, while ordinary judge-model calls are often much smaller than the platform fee itself, and Humanloop cannot be priced at all. Anthropic acquired Humanloop in 2025, and its pricing is entirely custom-quoted (QUOTE-ONLY / UNKNOWN); this article prices Braintrust and LangSmith and treats Humanloop as a comparison point without numbers.
At 100,000 eval runs a month with a deterministic grader, the platform cost is $324 on Braintrust Pro and $514 on LangSmith Plus once LangSmith's extended-retention upgrade fee is correctly included (every graded run, deterministic or judge-based, triggers that upgrade), and the judge and human-review cost is $0. Add one LLM judge per test and the judge model cost alone is about $48 per 100,000 runs.
Add a three-judge ensemble plus a 5% human-review sample at 3 minutes each, and human review becomes the dominant line at $8,750 per 100,000 runs, roughly 14 times the $632 Braintrust platform fee at that volume.
At 100,000 eval runs a month with a deterministic grader, the platform cost is $324 on Braintrust Pro and $514 on LangSmith Plus once LangSmith's extended-retention upgrade fee is correctly included (every graded run, deterministic or judge-based, triggers that upgrade). The judge and human-review cost is $0. Add one LLM judge per test and the judge model cost alone is about $48 per 100,000 runs. Add a three-judge ensemble plus a 5% human-review sample at 3 minutes each, and human review becomes the dominant line at $8,750 per 100,000 runs, roughly 14 times the $632 Braintrust platform fee at that volume.
My practical rule of thumb: don't agonize over which platform is $190 cheaper until you've decided how much human review you actually need. That decision moves your bill far more than the logo on the dashboard.
How evaluation platforms meter your test runs
Reliable AI products need solid automated testing before code ships. In 2026, most teams have moved away from ad-hoc manual prompt checks toward systematic evaluation pipelines. The catch is that each tool bills in a different way, so it helps to untangle what you're actually paying for:
- Braintrust meters scores and data volume: Scoring is the primary billing unit. The Starter tier is free for 10,000 scores, while Pro is $249 per month (including 50,000 scores, then $1.50 per 1,000 scores). It also meters processed dataset volume (5 GB included on Pro, then $3/GB). Every evaluation check that yields a metric increments the score meter, whether it's a quick Python regex, an LLM judge, or a human rater. Team seats are completely unlimited.
- LangSmith meters execution traces and data retention: Evaluation runs are recorded as traces. The Plus tier costs $39 per user seat per month and includes 10,000 base traces, with additional traces billed at $2.50 per 1,000. Here's the part that's easy to miss: when an evaluation score or feedback annotation is attached to a trace, LangSmith automatically upgrades that trace to Extended Data Retention (400-day retention), adding an extra $2.50 per 1,000. So any graded evaluation trace effectively costs $5.00 per 1,000 traces ($2.50 base + $2.50 retention upgrade).
- Humanloop is custom enterprise only: After its acquisition by Anthropic in 2025, Humanloop discontinued self-serve credit card pricing. Access is limited to annual enterprise agreements via direct sales quotes.
The three evaluation shapes: Deterministic, LLM-as-a-Judge, and Human-in-the-Loop
Not all eval runs are created equal, so we model three common testing patterns:
- Shape A (Deterministic / Code Grader): Fast automated assertions. A Python script verifies JSON syntax, regex patterns, keyword inclusions, or exact string matches. Model judge cost is $0, and human labor is $0.
- Shape B (Single LLM Judge): An automated model (such as GPT-4o-mini or Claude Haiku) evaluates output quality, factual accuracy, or helpfulness against reference criteria. Judge token cost is modest ($48 per 100,000 runs).
- Shape C (Ensemble Judges + 5% Human QA): A rigorous production gate with a three-judge consensus ensemble, plus 5% of runs sampled for human engineer review (3 minutes per review at $85/hour).
Platform, judge and human cost per volume
A quick note on assumptions so the table below is easy to trust:
- LangSmith seats scale with volume: 1 seat at 10,000 and 100,000 eval runs a month, 3 at 1 million (ILLUSTRATIVE).
- Braintrust processed-data volume scales with grading complexity: 0.001, 0.002 and 0.004 GB per 1,000 runs for shapes A, B and C respectively (ILLUSTRATIVE).
- For shape C, each of the three LLM judges is treated as a separately metered Braintrust score. The 5%-sampled human annotation counts as a fourth score on only those sampled runs, for an average of 3.05 scores per run.
- Braintrust's plan choice for each row is whichever of Starter or Pro produces the lower total cost at that shape's actual score and gigabyte volume, not an assumption about which plan the workload "should" need.
| Shape and volume | Platform (Braintrust) | Platform (LangSmith) | Judge model cost | Human review cost |
|---|---|---|---|---|
| A, 10,000 runs | $0 | $64 | $0 | $0 |
| A, 100,000 runs | $324 | $514 | $0 | $0 |
| A, 1,000,000 runs | $1,674 | $5,092 | $0 | $0 |
| B, 10,000 runs | $0 | $64 | $5 | $0 |
| B, 100,000 runs | $324 | $514 | $48 | $0 |
| B, 1,000,000 runs | $1,674 | $5,092 | $475 | $0 |
| C, 10,000 runs | $51 (Starter) | $64 | $14 | $875 |
| C, 100,000 runs | $632 (Pro) | $514 | $142 | $8,750 |
| C, 1,000,000 runs | $4,749 (Pro) | $5,092 | $1,425 | $87,500 |
At low volume (10,000 runs), deterministic testing is effectively free on Braintrust's Starter tier ($0) and costs just $64 on LangSmith (1 seat + base traces).
At 100,000 runs, platform fees rise predictably: $324 on Braintrust Pro and $514 on LangSmith Plus. Then look at Shape C. The moment a team adds a modest 5% human verification sample, human engineering labor jumps to $8,750 per month. At 1 million runs, that human review cost grows to a jaw-dropping $87,500 per month, dwarfing both platform subscriptions.
Total cost per 100,000 evals
Formula: total = platform + judge model cost + human review cost, scaled to a 100,000-run baseline.
| Shape | Braintrust total per 100,000 evals | LangSmith total per 100,000 evals |
|---|---|---|
| A: deterministic | $324 | $514 |
| B: one LLM judge | $372 | $562 |
| C: three-judge + 5% human | $9,525 | $9,406 |
Looking at totals at 100,000 runs shows where the budget really goes. In Shapes A and B, LangSmith runs roughly 50% to 59% higher than Braintrust ($514 vs $324 and $562 vs $372), because LangSmith's extended-retention upgrade fee applies to all scored traces.
In Shape C, though, human review is over 92% of the total monthly bill on both platforms. Choosing Braintrust ($9,525) or LangSmith ($9,406) makes less than a 1.5% difference to your overall monthly evaluation spend. In real-world production, that means the platform comparison matters most for the lighter shapes, and for the heavy one your review process is the thing to optimize.
Cost of repeated regression suites
A regression suite of 200 test cases that runs on every merge is a different volume driver than ad hoc evaluation. Formula: monthly eval runs = test cases × suite runs per month. For the separate trace-storage and retention budget, compare LangSmith, Langfuse and Arize observability costs rather than equating an eval run with a stored trace.
| Suite runs per month | Monthly eval runs (200-case suite) | Judge cost (one judge per case) |
|---|---|---|
| 4 (weekly) | 800 | under $1 |
| 20 (daily on business days) | 4,000 | $2 |
| 100 (multiple times per merge, active team) | 20,000 | $10 |
Wiring evaluation suites into GitHub Actions or GitLab CI pull request workflows is pleasantly cheap when you lean on lightweight automated judges. A standard 200-test-case suite on every code commit costs less than $10 per month in LLM judge tokens, even for very active teams running 100 regression passes monthly. Automated regression testing is the cheap part. The expensive part is letting an unvetted model regression reach your users.
Break-even: QA and engineering hours saved
Formula: hours needed = monthly cost ÷ loaded hourly cost, with $85 an hour for a QA or ML engineer (ILLUSTRATIVE). Think of this as a threshold: the eval pipeline pays for itself if it prevents or catches this many hours of manual investigation. It's not a promise that it will.
| Case (100,000 runs/month) | Total monthly cost | Hours to break even |
|---|---|---|
| Braintrust, shape A | $324 | 3.8 |
| LangSmith, shape B | $562 | 6.6 |
| Braintrust, shape C | $9,525 | 112.1 |
| LangSmith, shape C | $9,406 | 110.7 |
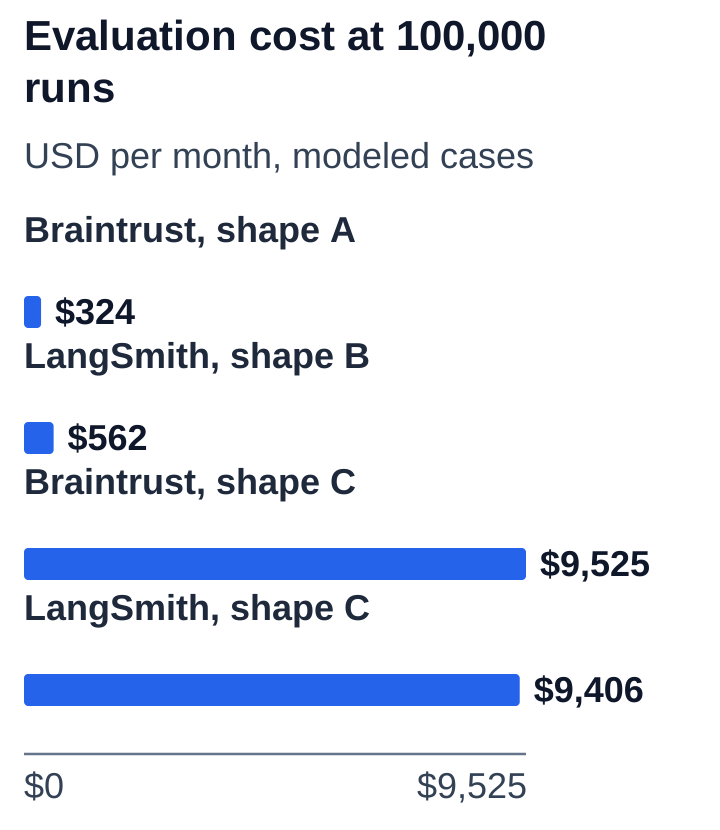
At a loaded engineering rate of $85 per hour, an automated evaluation suite on Shape A pays for itself if it catches bugs that would have eaten just 3.8 hours of manual debugging per month. On Shape B (single LLM judge), the break-even threshold is 6.6 engineering hours. Most teams can clear those bars with a single bad Friday deploy.
Shape C needs to save roughly 110–112 engineering hours (nearly three full engineer-weeks) to break even. That's realistic mainly for high-stakes workflows like medical diagnostics, financial compliance, or customer-facing contract analysis, where one production hallucination could carry serious commercial liability. If your team relies on that level of rigor daily, the spend is justified. If it's a nice-to-have, save your budget for Shapes A and B.
Architectural recommendations for evaluation budgets
- Implement a tiered evaluation funnel: Avoid running expensive multi-judge ensembles or human review on raw prompt outputs. Filter outputs through fast, free deterministic assertions first (Shape A). If those pass, trigger a lightweight, low-cost LLM judge (Shape B). Save human-in-the-loop review for runs where the automated judge reports low confidence or borderline scores.
- Watch LangSmith's retention upgrade: Attaching evaluators to dataset runs automatically triggers LangSmith's extended retention fee ($2.50/1k on top of base traces). If you run millions of ephemeral CI smoke tests, consider isolating transient test traces from long-term production monitoring datasets.
- Audit judge model token limits: When configuring automated LLM judges, keep evaluation prompts concise and strictly limit
max_tokenson judge completions. That keeps model evaluation tokens under $50 per 100,000 runs.