AWS Bedrock Guardrails vs Azure AI Content Safety vs OpenAI Moderation: Real AI Safety Cost per 1 Million Requests in 2026
The bottom line: OpenAI's Moderation endpoint is free and screens both text and images against OpenAI's fixed taxonomy, with no per-call charge and no usage-limit impact. The catch is that it only checks OpenAI's own categories, not a custom policy. AWS Bedrock Guardrails and Azure AI Content Safety both charge per unit of text screened, and both round a partial unit up to a full one (AWS's own documentation confirms this explicitly). In a typical setup, both also bill twice per request: once for the user's input and once for the model's output.
At an ILLUSTRATIVE 500 characters per screening pass, that rounding means each pass consumes one full billed unit, not half of one. So 1 million requests costs about $1,500 on AWS Bedrock Guardrails at a REPORTED $0.75-per-1,000-unit blanket rate. That figure conflicts with an official EU pricing page's more granular content-filter figure of roughly $559, and with a separately reported, more recently dated $0.15-per-1,000-unit rate that would put the same volume at about $300. On Azure AI Content Safety, the same volume runs about $2,000.
Guardrail cost isn't a rounding error at scale. One industry analysis noted that for high-volume applications, guardrail costs can exceed the underlying model's own inference cost. My practical rule of thumb: if basic toxicity screening satisfies your compliance needs, start with the free option. Pay for a managed guardrail only when you genuinely need custom policy control.
What each vendor bills
Content safety tools add a brand-new line item to your production bill, and each major provider approaches it a little differently.
OpenAI provides its Moderation endpoint completely free of charge for developers using OpenAI models. It evaluates text and images against standard safety categories (including hate, harassment, self-harm, sexual content, and violence) without per-call fees or rate limit deductions. What to keep in mind is that it offers zero customization. You can't add custom regex rules, mask PII, enforce proprietary topic restrictions, or verify factual grounding against reference documents.
AWS Bedrock Guardrails bills based on text units screened, with standard blanket pricing typically reported at $0.75 per 1,000 text units (where one text unit equals up to 1,000 characters). The documentation reflects varying regional rate cards, including EU content-filter tiers around $0.28 per 1,000 units and newer reported rates near $0.15. In return for the spend, Bedrock gives you granular policy control that OpenAI doesn't: custom topic filters, regex-based PII redaction, prompt injection defense, and contextual grounding checks to flag hallucinations.
Azure AI Content Safety bills per 1,000 text records (up to 1,000 characters per record), with standard production rates around $1.00 to $1.50 per 1,000 records ($200 per 100,000 requests on two-pass screening). Azure provides multi-severity scoring across core safety categories, prompt shields against direct jailbreaks, and detection for protected material.
Both input and output get screened
In production, comprehensive content safety means two evaluation passes per interaction:
- Prompt Screening: Check the user's prompt before it reaches the language model, to intercept prompt injection attempts, toxic phrasing, and prohibited topics.
- Response Screening: Check the model's generated answer before the user sees it, to catch hallucinations, unintended PII leakage, or policy violations.
Because AWS and Azure round partial units up to the next full 1,000-character boundary, a 400-character user prompt counts as one full unit, and a 600-character completion counts as a second unit. Every end-to-end request consumes two full billing units.
Cost per volume
Here's the cumulative cost of content safety screening across monthly request volumes. It assumes standard two-pass screening (input prompt + output response) with partial 1,000-character units rounding up:
| Requests/month | AWS (REPORTED $0.75/1k blanket rate) | AWS (OFFICIAL EU content-filter rate, ~$0.28/1k) | AWS (REPORTED newer $0.15/1k rate) | Azure AI Content Safety | OpenAI Moderation |
|---|---|---|---|---|---|
| 100,000 | $150.00 | $55.89 | $30.00 | $200.00 | $0 |
| 1,000,000 | $1,500.00 | $558.86 | $300.00 | $2,000.00 | $0 |
| 10,000,000 | $15,000.00 | $5,588.57 | $3,000.00 | $20,000.00 | $0 |
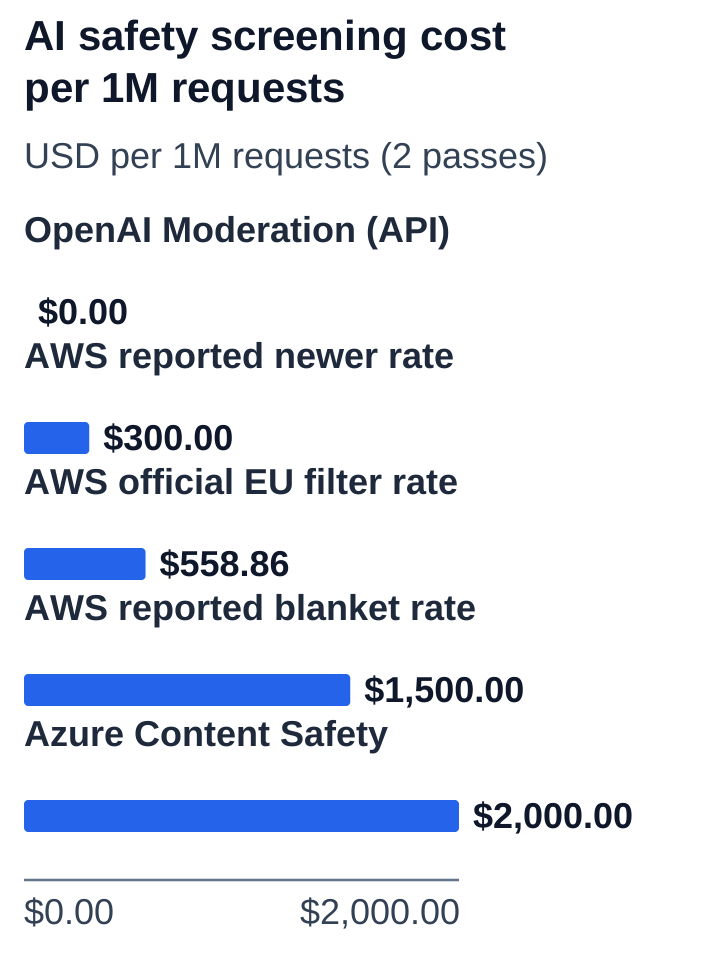
At 10 million monthly requests, commercial guardrails add $15,000 to $20,000 per month on standard rates, compared to zero additional software fees for OpenAI Moderation.
The spread between AWS's three rate columns is wide enough that I'd confirm your actual region and current rate card before putting any of these numbers in a budget deck.
When guardrail cost exceeds the model's own cost
As small, specialized models get faster and cheaper, you can hit an unexpected inversion: the safety filter can cost more than the language model itself.
Say you're running a lightweight model like Llama 3.2 1B or Phi-4-mini at roughly $0.05 to $0.10 per million tokens. A quick user prompt of 100 tokens with a 50-token answer costs less than $0.00002 in inference. Run that same interaction through two passes of commercial guardrails ($1.50 to $2.00 per 1,000 requests total) and it costs $0.00150 to $0.00200. That makes safety inspection 75 to 100 times more expensive than running the model.
Even with mid-tier models, guardrail inspection is a substantial slice of total pipeline cost, not an afterthought. In real-world production, this means you should price the guardrail and the model together, not separately.
Sensitivity
A few knobs move this bill more than you'd expect:
- Screening Passes (Single vs. Dual): Screening only incoming user prompts cuts safety costs in half, but leaves you exposed to hallucinated or inappropriate model completions.
- Text Unit Rounding: Verbose user queries or detailed RAG context passages that exceed 1,000 characters immediately roll into additional billed units, multiplying safety costs.
- Advanced Evaluation Filters: Enabling contextual grounding or automated hallucination detection on Bedrock adds separate evaluation fees on top of standard content filters.
- Custom Compliance Requirements: If you need strict PII redaction or company-specific topic bans, free tools like OpenAI Moderation won't cover you, and you'll need to budget for commercial guardrail tiers.
Budgeting traps
These are the ones that tend to surprise people on the first invoice:
- Budgeting for only one pass: Assuming guardrails only inspect user inputs overlooks the need to screen model responses before delivery.
- Ignoring small-model cost inversions: Pairing high-volume lightweight models with managed guardrails without realizing the safety checks will drive the majority of the invoice.
- Over-screening internal administrative traffic: Applying full multi-tier guardrail pipelines to trusted internal automation where security risks are already governed by role-based access.
- Uncontrolled document context screening: Passing lengthy retrieved RAG documents through guardrails rather than screening only the core user query.
What to ask before you buy
Start with a few honest questions:
- Do your compliance guidelines mandate custom topic filtering, PII redaction, or hallucination detection, or does basic toxicity screening satisfy requirements?
- Can you screen incoming prompts while relying on model system prompts for output hygiene on internal tools?
- What is the combined per-request cost when running lightweight models behind managed safety endpoints?
If your answers lean toward "basic screening is fine," the free endpoint will likely serve you well. If your compliance team needs custom policies, the paid tiers earn their keep. Either way, run the numbers on your own request volume first.